BLIP-2 Flan-T5-XL
Answers questions about one image or captions it, using Google's instruction-tuned Flan-T5-XL as the language model inside BLIP-2. Only the answer text comes back.


Overview
Salesforce paired its BLIP-2 method here with Flan-T5-XL, Google's instruction-tuned encoder-decoder language model. Image features come from a CLIP-like encoder. Neither the encoder nor Flan-T5-XL was retrained; their weights were loaded from existing checkpoints and frozen. Training went into a BERT-like Querying Transformer, which maps a set of learned query tokens to embeddings that Flan-T5-XL reads together with your prompt. The checkpoint holds about 3.9 billion parameters.
In the BLIP-2 paper, the Flan-T5 versions beat the OPT versions on zero-shot visual question answering, and the authors cite this as evidence that a stronger language model gives better results. This checkpoint is the pre-trained release, with no task-specific fine-tuning on top.
What you can build
- Counting and attribute questions about listing photos, such as how many chairs a room has.
- A research prototype that asks whether each photo in a labeled set shows a dog and compares every yes/no reply with the human label.
- A short chat about one picture, with earlier turns pasted back into the prompt. The model card lists this chat-like use.
Inputs
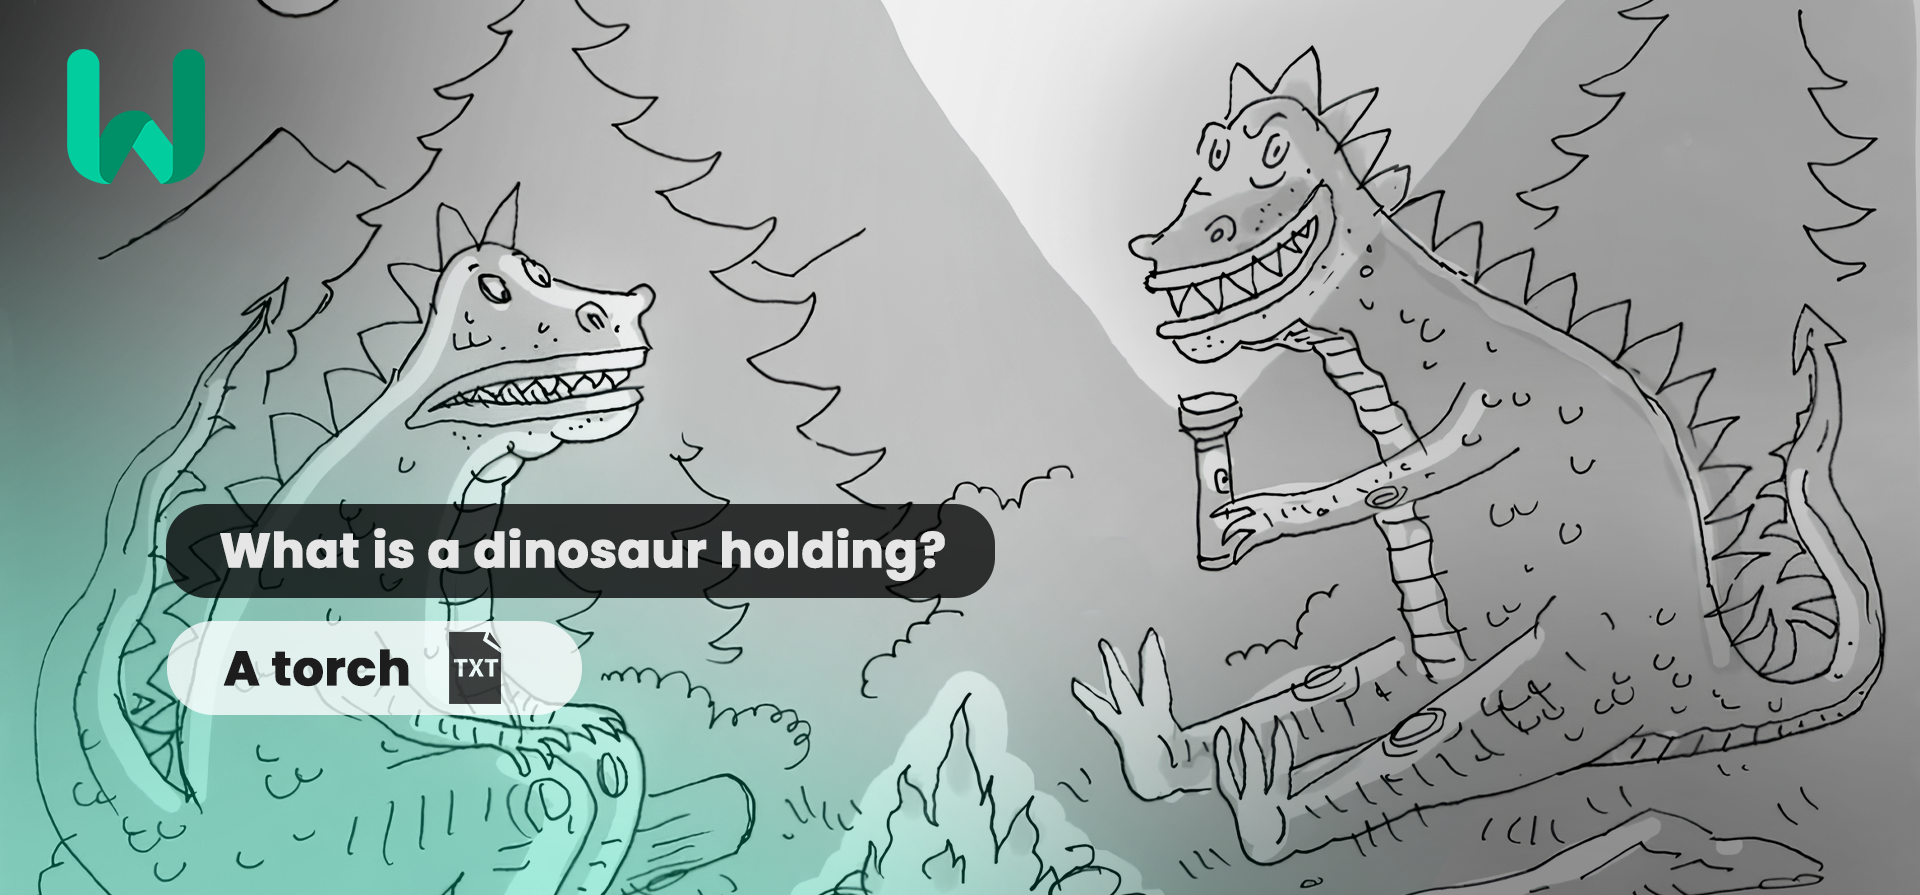
An image is required. Upload a JPG, JPEG, PNG, GIF, WEBP or HEIC file, or paste the image's link into the same field. The prompt is optional and comes prefilled with a question about what the dinosaur is holding. A token limit between 1 and 500 (30 by default) sets the ceiling on answer length.
Outputs
You get plain text containing just the answer; the question is not repeated. Both samples on this page are short lowercase phrases. The Eiffel Tower photo comes back as "the eiffel tower". Asked the default question about what a dinosaur is holding, the campfire cartoon returns "a fire", although the dinosaur on the right holds a flashlight.
Recommended settings
- Phrase the prompt as a direct question or a short instruction. Flan-T5 was fine-tuned on instruction-style prompts.
- To continue a conversation, put the earlier questions and answers in the prompt ahead of the new question.
- 30 tokens is enough for answers like the samples. Raise it if a longer caption gets cut off.
Limitations
- The Flan-T5 card warns that language models, Flan-T5 included, can be used to generate harmful language. BLIP-2 runs Flan-T5 unchanged and inherits that risk.
- Its image-text training data was collected from the internet, LAION among it, so the model may reproduce biases or inappropriate content found there.
- Write prompts in English. It is the only language the card lists.
Safety & compliance
Salesforce publishes the checkpoint under the MIT license. Its Flan-T5-XL weights were released by Google under Apache 2.0. According to the model card, this release is for research purposes only, in support of an academic paper. BLIP-2 has not been tested in real-world applications. The card says it should not be deployed directly in any application, and that researchers should first assess its safety and fairness for the context they plan to use it in. When an image shows a real person, upload it only with that person's consent.
API quick start
Run blip2-flan-t5-xl with a single API call.
{
  "prompt": "What is a dinosaur holding?",
  "inputImage": "https://your-cdn.com/input.png",
  "tokens": 30
}
curl -X POST "https://api.wiro.ai/v1/Run/salesforce/blip2-flan-t5-xl" \
-H "Content-Type: application/json" \
-H "x-api-key: YOUR_WIRO_API_KEY" \
--data-binary @- <<'JSON'
{
"prompt": "What is a dinosaur holding?",
"inputImage": "https://your-cdn.com/input.png",
"tokens": 30
}
JSONOther models you might like
Explore similar image generation models.