Try PixVerse C1 Reference-to-Video Model from PixVerse →
Models
Agents
Workflows
Studio
PricingBlogDocs
ExploreDiscover models by categoryBrowse All ModelsBrowse the complete catalogSee FavoritesSign in to view saved models
Generative Media AgentCreate and edit media by chattingWorkflow AgentBuild visual workflows with Agent
OverviewThe platform at a glanceLearnSkills, knowledge, guardrailsAnatomyWhat makes agents reasonBuild Your AgentPick skills, set tier, deploy
Pre-built AgentsBrowse the catalog
Agent Usecases
Ad Campaign ManagerApp Event ManagerApp Review RepliesBarber BookingCustomer Win-BackEcommerce ListingsRestaurant Reviews
Sign InStart Building

Task History

Click to see output list

No tasks yet

Go to Models
Discover AI models

Search the full model catalog.

Discover and compare production-ready models. Filter by modality, provider, pricing, and production fit.
553 models0 active filters

Wiro AI

Utilities

Video Generation

Text to VideoImage to VideoVideo to Video

Image Generation

Text to ImageImage to ImageImage EditingImage to Text

Audio & Speech

Text to SpeechSpeech to TextSpeech to SpeechVoice Clone

Realtime Stream

Realtime Conversation

Music Generation

Music Generation

3D Generation

LLM & Chat

LLM

Partners

Need help choosing?

Compare models by capability, cost, and provider fit.

Showing 461–480 of 553 models
caption - AI model cover image

caption

moondream3-preview

Moondream3 is a cutting-edge vision-language model that delivers advanced visual reasoning with built-in object detection, pointing, and OCR capabilities—bringing fast, cost-effective, and scalable inference to real-world applications.

Image to Textbf16image-to-text
Run
query - AI model cover image

query

moondream3-preview

Moondream3 is a cutting-edge vision-language model that delivers advanced visual reasoning with built-in object detection, pointing, and OCR capabilities—bringing fast, cost-effective, and scalable inference to real-world applications.

Image to Textbf16image-to-text
Run
gpt-oss-20b - AI model cover image

gpt-oss-20b

openai

OpenAI GPT-OSS-20B model.

Chattext generationtransformers
Run
Qwen3-30B-A3B - AI model cover image

Qwen3-30B-A3B

Qwen

Qwen3-30B-A3B model.

Chattext generationtransformers
Run
Qwen3-30B-A3B-Thinking-2507 - AI model cover image

Qwen3-30B-A3B-Thinking-2507

Qwen

Qwen3-30B-A3B-Thinking-2507 model.

Chattext generationtransformers
Run
Qwen3-32B - AI model cover image

Qwen3-32B

Qwen

Qwen3-32B model.

Chattext generationtransformers
Run
Qwen3-Coder-30B-A3B-Instruct - AI model cover image

Qwen3-Coder-30B-A3B-Instruct

Qwen

Qwen3-Coder-30B-A3B-Instruct model.

Chattext generationtransformers
Run
whisper-large-v3-turbo-turkish - AI model cover image

whisper-large-v3-turbo-turkish

openai

Whisper is a pre-trained model for automatic speech recognition (ASR) and speech translation. Trained on 680k hours of labelled data, Whisper models demonstrate a strong ability to generalise to many datasets and domains without the need for fine-tuning.

Speech to Textspeech-to-textwhisper
Run
Face-Swap - AI model cover image

Face-Swap

wiro

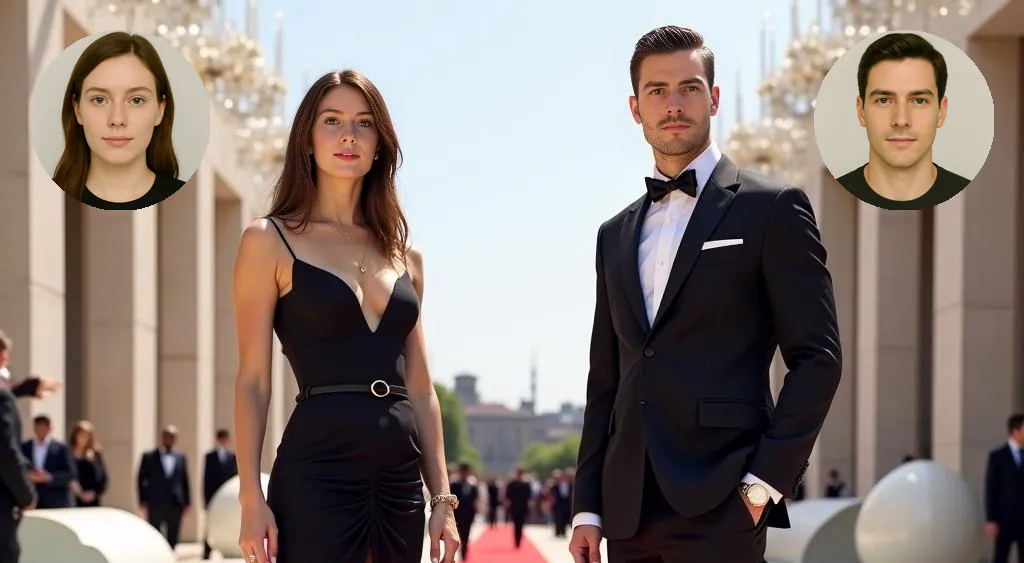
Puts one or two faces into a scene it generates from your prompt, or into a photo you upload. In a two-person photo it can replace just the left or the right person.

Image to Imagerestoration
Run
SenecaLLM-x-QwQ-32B-Q8_Max-Version - AI model cover image

SenecaLLM-x-QwQ-32B-Q8_Max-Version

AlicanKiraz0

Mixed dataset LLM Information Security v1.5 - Incident Response v1.3.1 - Threat Hunting v1.3.2 - Ethical Exploit Development v2.0 - Purple Team Tactics v1.3 - Reverse Engineering v2.0

Chattext generationtransformers
Run
train-flux-lora-portrait - AI model cover image

train-flux-lora-portrait

wiro

Fast LoRA training is a technique used to fine-tune FLUX models, enabling personalized model outputs with fast.

Text to Image
Run

SkyReels-V1

wiro

SkyReels V1 is the first and most advanced open-source human-centric video model.

Image to Video
Run
deepseek-vl2 - AI model cover image

deepseek-vl2

deepseek-ai

DeepSeek-VL2 delivers accurate and fast answers to your questions about images, making visual question answering effortless and reliable.

Run
video-nsfw-detection - AI model cover image

video-nsfw-detection

wiro

NSFW video detection automatically analyzes video content to identify inappropriate or explicit material, ensuring compliance with content policies and a safe viewing environment.

Video to Textvideo
Run
stable-diffusion-3.5-large - AI model cover image

stable-diffusion-3.5-large

stabilityai

Stable Diffusion 3.5 Large is a Multimodal Diffusion Transformer (MMDiT) text-to-image model that features improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.

Text to Imagetext-to-imagediffusers
Run
VideoLLaMA3-2B - AI model cover image

VideoLLaMA3-2B

DAMO-NLP-SG

VideoLLaMA3-2B is a model designed for video understanding.

Video to Text
Run
VideoLLaMA3-2B-Image - AI model cover image

VideoLLaMA3-2B-Image

DAMO-NLP-SG

VideoLLaMA3-2B-Image is a model designed for image understanding.

Image to Text
Run
Qwen2.5-14B-Instruct - AI model cover image

Qwen2.5-14B-Instruct

Qwen

Qwen2.5-14B-Instruct is a large language model by Alibaba’s Qwen team, optimized for instruction-following tasks with 14 billion parameters. It offers strong reasoning, multilingual capabilities, and efficient performance, making it suitable for chatbots, content creation, and various AI-driven applications.

Chattext generationtransformers
Run
Qwen2.5-32B-Instruct - AI model cover image

Qwen2.5-32B-Instruct

Qwen

Qwen2.5-32B-Instruct is a powerful large language model developed by Alibaba’s Qwen team, designed for instruction-following tasks with enhanced reasoning and natural language understanding capabilities. Optimized for efficiency and accuracy, it supports multi-turn conversations and complex queries, making it suitable for applications such as chatbots, content generation, and AI assistants.

Chattext generationtransformers
Run
Sana_1600M_2Kpx_BF16_diffusers - AI model cover image

Sana_1600M_2Kpx_BF16_diffusers

Efficient-Large-Model

Sana is a text-to-image framework that can efficiently generate images up to 4096 × 4096 resolution.

Text to Imagetext-to-imagesana
Run
Showing 461–480 of 553 models
  • 1
  • …
  • 22
  • 23
  • 24
  • 25
  • 26
  • …
  • 28

Discover, test, and run AI models, build workflows and agents with one unified API.

All systems operational
WiroModelsAgentsPricingAboutBlogCareersContactPartnerChangelogStatusFAQ
CategoriesText to ImageImage to ImageImage EditingImage to TextText to VideoImage to VideoVideo to VideoText to SpeechSpeech to TextSpeech to SpeechVoice CloneRealtime ConversationMusic GenerationLLMUtilities
ModelsNano Banana 2GPT Image 2.5Seedream V5 ProSeedance 2.5Veo 3.1Kling V3FLUX 3FLUX.2 ProWan 3.0 PrimeGrok Imagine 1.5
PartnersGoogleOpenAIByteDanceBlack Forest LabsKling AIQwenAlibabaxAIMiniMaxElevenLabs
Getting StartedIntroductionAuthenticationProjectsCode ExamplesWiro MCP ServerSelf-Hosted MCPn8n IntegrationLLMs.txt
API ReferenceModelsRun a ModelModel ParametersTasksLLM & Chat StreamingWebSocketRealtime VoiceFiles
© 2026 Wiro AI. All rights reserved.
PrivacyTermsData Deletion