ElevenLabs Speech-to-Speech v2 Voice Changer API
Re-voice an existing recording with a chosen ElevenLabs voice while keeping the original words, timing, and delivery. Export MP3 in common 22.05 kHz and 44.1 kHz presets.
Overview
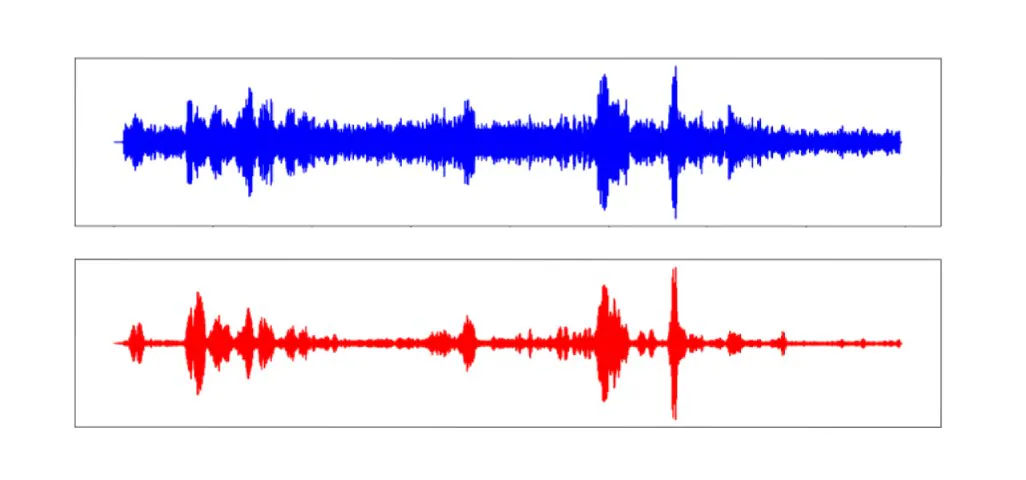
Speech-to-Speech v2 is an audio-to-audio voice conversion model by ElevenLabs. You upload a spoken recording, then the model re-synthesizes it in a new voice while keeping the original timing, pacing, and pauses. It’s useful when you want the same performance and delivery but need a different speaker for narration, characters, or corrections.
What you can build
- Re-voice a creator’s take into a consistent character voice for a series
- Replace a scratch track with a production voice without re-recording timing
- Create multilingual character performances when paired with a matching voice
- Fix voice continuity across recording sessions with different microphones
- Produce alternate voice versions for A/B testing in ads or product videos
Inputs
- A single-speaker audio recording you want to re-voice. Provide a common audio file (such as MP3). The model keeps the words and pacing from this recording.
- A target voice selection that defines who the output should sound like.
- An output quality preset for MP3 export, defined by sample rate and bitrate.
- Optional background-noise removal that strips room hiss and ambience before conversion.
- Optional voice control sliders that adjust how consistent and deterministic the target voice sounds across renders.
- Optional similarity control that pushes the output closer to the chosen target voice, which can also pull in artifacts from noisy inputs.
- Optional style exaggeration that makes the result more expressive but can reduce stability.
- Optional speaker boost that increases resemblance to the chosen voice, with a higher risk of artifacts in some cases.
Outputs
The model returns a single audio file as MP3. The output contains the same spoken content and timing as your source recording, but rendered with the selected target voice. The MP3 is delivered in the quality preset you chose, such as 44.1 kHz at 128 kbps.
Recommended settings
- General voice conversion: keep stability near 0.5, similarity near 0.75, and style at 0.
- Noisy phone or room audio: enable background-noise removal, then avoid very high similarity.
- Dramatic delivery: lower stability and raise style slightly, then regenerate until you like the take.
- Maximum consistency across many clips: raise stability and keep style at 0.
Limitations
- Maximum segment length is 5 minutes. Split longer recordings into chunks.
- Output quality depends heavily on input quality. Reverb, clipping, and heavy compression can create artifacts.
- Multiple speakers in one clip can confuse the conversion and cause voice drift.
- Background-noise removal can thin out clean studio audio and reduce natural ambience.
- Language coverage depends on the underlying Speech-to-Speech model and chosen voice. The multilingual v2 Speech-to-Speech model supports 29 languages, while the English Speech-to-Speech v2 model supports English only.
Safety & compliance
- Only convert or clone voices when you have consent and the legal right to do so.
- Don’t use the model for deceptive impersonation, fraud, scams, or harmful misinformation.
- Don’t use it to enable unauthorized robocalling, spam, or harassment.
- Follow ElevenLabs Terms of Service and Prohibited Use Policy for all inputs and outputs.
API quick start
Run speech-to-speech-v2 with a single API call.
{
  "inputAudio": "https://your-cdn.com/input.mp3",
  "voice": "alice",
  "outputFormat": "mp3_44100_128",
  "removeNoise": "false"
}
curl -X POST "https://api.wiro.ai/v1/Run/elevenlabs/speech-to-speech-v2" \
-H "Content-Type: application/json" \
-H "x-api-key: YOUR_WIRO_API_KEY" \
--data-binary @- <<'JSON'
{
"inputAudio": "https://your-cdn.com/input.mp3",
"voice": "alice",
"outputFormat": "mp3_44100_128",
"removeNoise": "false"
}
JSONOther models you might like
Explore similar audio & speech models.