Filters0 active

Wiro AI

Video Generation

Image Generation

Audio & Speech

Realtime Stream

Music Generation

3D Generation

LLM & Chat

Partners

Try Kling V4 Video Generator from Kling-AI →
Models
Agents
Workflows
Studio
PricingBlogDocs
ExploreDiscover models by categoryDiscoverModels and effects built by WiroBrowse All ModelsBrowse the complete catalogSee FavoritesSign in to view saved models
Generative Media AgentCreate and edit media by chattingWorkflow AgentBuild visual workflows with Agent
OverviewThe platform at a glanceLearnSkills, knowledge, guardrailsAnatomyWhat makes agents reasonBuild Your AgentPick connectors and skills, set tier, deploy
Pre-built AgentsBrowse the catalog
Agent Usecases
Ad Campaign ManagerApp Event ManagerApp Review RepliesBarber BookingCustomer Win-BackEcommerce ListingsRestaurant Reviews
Sign InStart Building
Discover AI models

Search the full model catalog.

Discover and compare production-ready models. Filter by modality, provider, pricing, and production fit.
AI Models and Tools

555 models0 active filters

Wiro AI

Utilities

Video Generation

Text to VideoImage to VideoVideo to Video

Image Generation

Text to ImageImage to ImageImage EditingImage to Text

Audio & Speech

Text to SpeechSpeech to TextSpeech to SpeechVoice Clone

Realtime Stream

Realtime Conversation

Music Generation

Music Generation

3D Generation

LLM & Chat

LLM

Partners

Need help choosing?

Compare models by capability, cost, and provider fit.

Showing 541–555 of 555 models
FLUX.1-Fill-dev - AI model cover image

FLUX.1-Fill-dev

black-forest-labs

Inpainting and outpainting model from Black Forest Labs. Upload a photo and a mask, describe what belongs in the masked area, and only that area is repainted to fit the rest of the image.

Image to Imagediffusersfluxfillpipeline
Run
vlm-image-to-text - AI model cover image

vlm-image-to-text

wiro

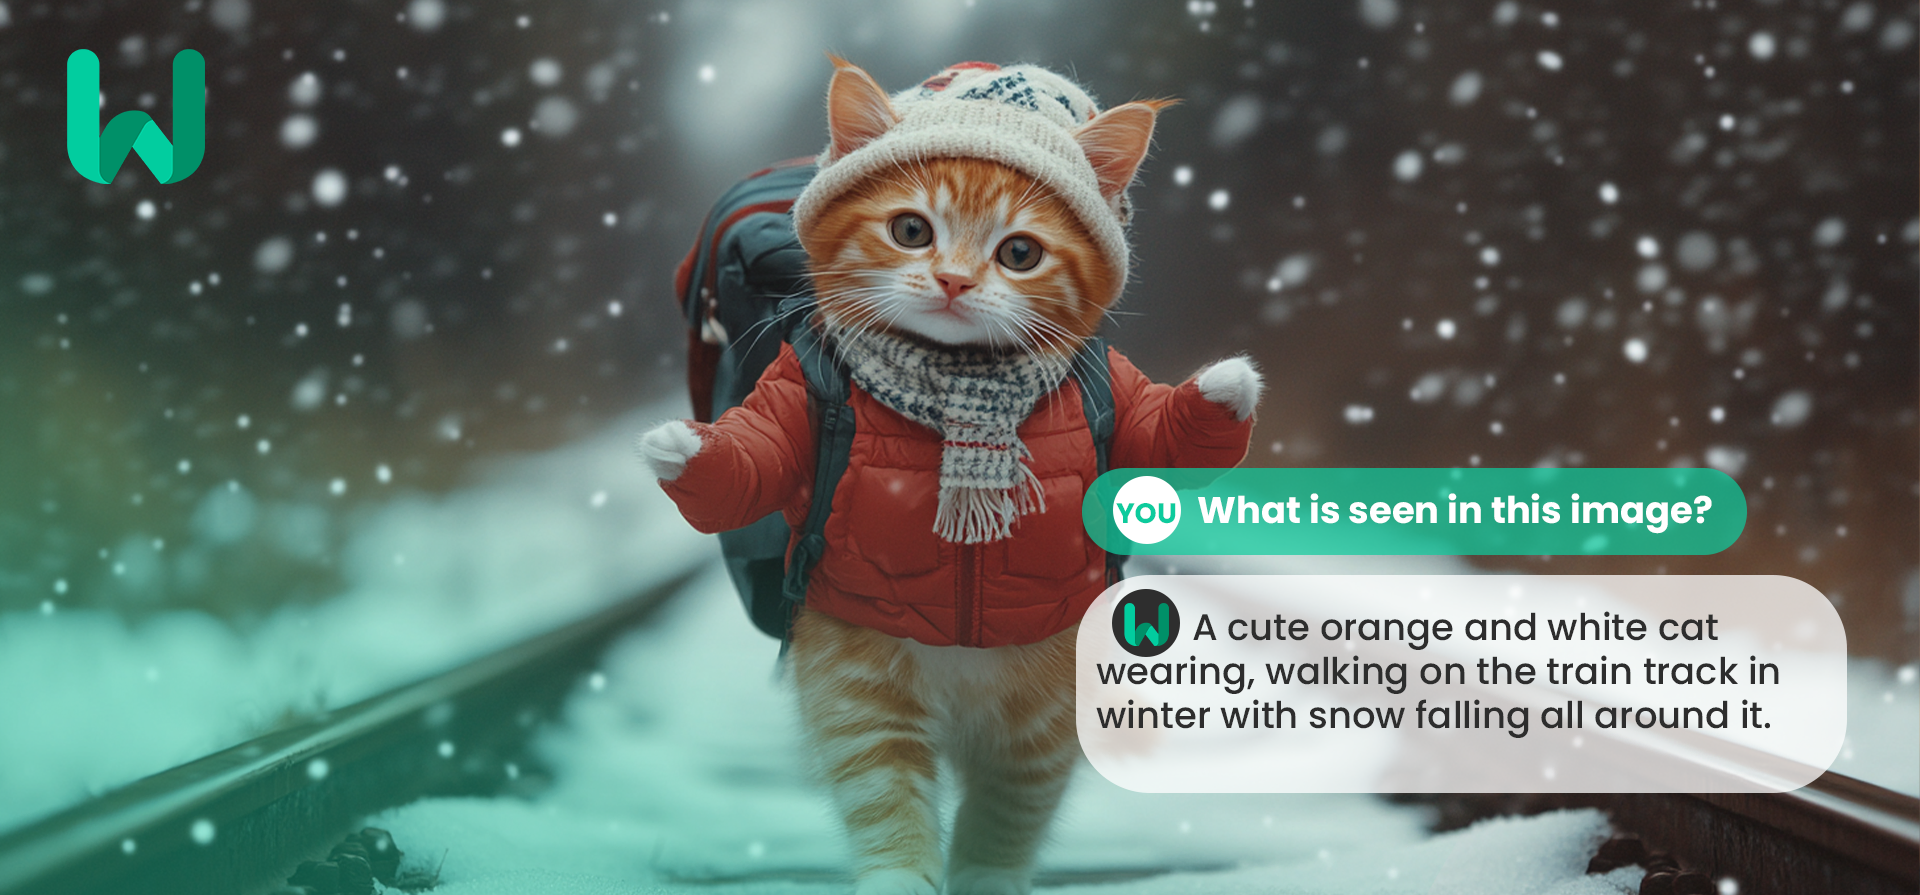
Runs a vision language model of your choice on an image and returns its answer to your question as text. LLaVA v1.6 Mistral 7B is selected by default.

Image to Text
Run
Llama-2-7b-chat-hf - AI model cover image

Llama-2-7b-chat-hf

meta-llama

Meta's 7B Llama 2 chat model, aligned for English dialogue with supervised fine-tuning and RLHF. Text in, text out, with a 4k-token context window.

Chattext-generation-inferencellama2-chat
Run
FLUX.1-dev - AI model cover image

FLUX.1-dev

black-forest-labs

FLUX.1 Dev is Black Forest Labs' 12B open-weight text-to-image model, distilled from FLUX.1 [pro]. It can spell short text inside the image, like the words on a sign or a label.

Text to Image
Run

live-portrait

wiro

Make your portrait alive! It is a tool that turns your portrait into a video using a provided reference video.

Video to Video
Run
stable-diffusion-3-medium - AI model cover image

stable-diffusion-3-medium

stabilityai

Stability AI's 2-billion-parameter MMDiT text-to-image model from the SD3 series. It reads prompts through three text encoders, and Stability AI reports fewer spelling and spacing errors in rendered text.

Text to Imagetext-to-imagediffusers
Run
PixArt-XL-2-1024-MS - AI model cover image

PixArt-XL-2-1024-MS

PixArt-alpha

It generates high-resolution images from text.

Text to Image
Run
image-restoration - AI model cover image

image-restoration

wiro

Restores blurry, low-resolution photos: CodeFormer rebuilds the face nearest the center, and Real-ESRGAN doubles the whole frame before it is scaled to the upscale factor you set, up to 10.

Image to Image
Run
llava-v1.6-mistral-7b-hf - AI model cover image

llava-v1.6-mistral-7b-hf

llava-hf

LLaVA is a tool that generates descriptions for a given image.

Image to Text
Run

ani-portrait-audio2video

wiro

It creates a video by combining the input image with the movements of a person in a video and adding the audio from the input audio.

Audio To Video
Run

ani-portrait-pose2video

wiro

It creates a video by incorporating the movements and audio of a person from a given video into the input image.

Image to Video
Run
blip2-opt-2.7b - AI model cover image

blip2-opt-2.7b

Salesforce

BLIP-2 paired with Meta's OPT-2.7B. Send an image and a question to get a short text answer or caption, returned with your question in front of it.

Image to Text
Run
voice-clone - AI model cover image

voice-clone

wiro

Reads text aloud in the voice of a short reference clip. Built on Coqui's XTTS-v2, it needs about six seconds of speech, and the text can be in any of 17 languages, whatever language the clip is in.

Speech to Speech
Run
noise-reduction - AI model cover image

noise-reduction

librosa

Removes background noise from speech and field recordings with spectral gating, PCEN or a highpass filter, used alone or combined in one run.

Speech to Speechlibrosaaudio
Run
bark-dialogue - AI model cover image

bark-dialogue

suno-ai

Voices a multi-speaker script with Suno's Bark. You start each line with a label such as sp_1 or sp_2 and pick a voice preset per label; the conversation comes back as one MP3.

Text to Speechsuno-aibark
Run
  • 1
  • …
  • 23
  • 24
  • 25
  • 26
  • 27
  • 28

Discover, test, and run AI models, build workflows and agents with one unified API.

All systems operational
WiroModelsAgentsPricingAboutBlogCareersContactPartnerChangelogStatusFAQ
CategoriesText to ImageImage to ImageImage EditingImage to TextText to VideoImage to VideoVideo to VideoText to SpeechSpeech to TextSpeech to SpeechVoice CloneRealtime ConversationMusic GenerationLLMUtilities
ModelsNano Banana 2GPT Image 2.5Seedream V5 ProSeedance 2.5Veo 3.1Kling V3FLUX 3FLUX.2 ProWan 3.0 PrimeGrok Imagine 1.5
PartnersGoogleOpenAIByteDanceBlack Forest LabsKling AIQwenAlibabaxAIMiniMaxElevenLabs
Getting StartedWiro ModelsWiro EffectsIntroductionAuthenticationProjectsCode ExamplesWiro MCP ServerSelf-Hosted MCPn8n IntegrationLLMs.txt
API ReferenceModelsRun a ModelModel ParametersTasksLLM & Chat StreamingWebSocketRealtime VoiceFiles
© 2026 Wiro AI. All rights reserved.
PrivacyTermsData Deletion