Voice Clone
Reads text aloud in the voice of a short reference clip. Built on Coqui's XTTS-v2, it needs about six seconds of speech, and the text can be in any of 17 languages, whatever language the clip is in.


Overview
Voice Clone turns a line of text into speech in the voice of the person in your reference recording. It runs Coqui's XTTS-v2, which Coqui says needs only a 6-second clip of the target speaker. Nothing is trained per voice; each run takes the reference audio and the text and returns a new recording.
XTTS-v2 also clones across languages, so the reference and the output do not have to share one. An English recording can be used to read Turkish text, for example.
What you can build
- Voice prototypes and research demos that read new text in a consenting speaker's voice
- Cross-language tests where one speaker's voice reads the same text in several of the 17 languages
- Spoken prompts and personal voice messages inside an app
Inputs
- Reference audio: an MP3, WAV, OGG, M4A or WebM file, sent as a file or a public link. Use a recording of a single speaker.
- Prompt (required): the text to speak.
- Language: the language the prompt is written in. The list covers English, Spanish, French, German, Italian, Portuguese, Polish, Turkish, Russian, Dutch, Czech, Arabic, Chinese, Japanese, Hungarian, Korean and Hindi, with English as the default.
- Temperature: from 0 to 1, default 0.75.
Outputs
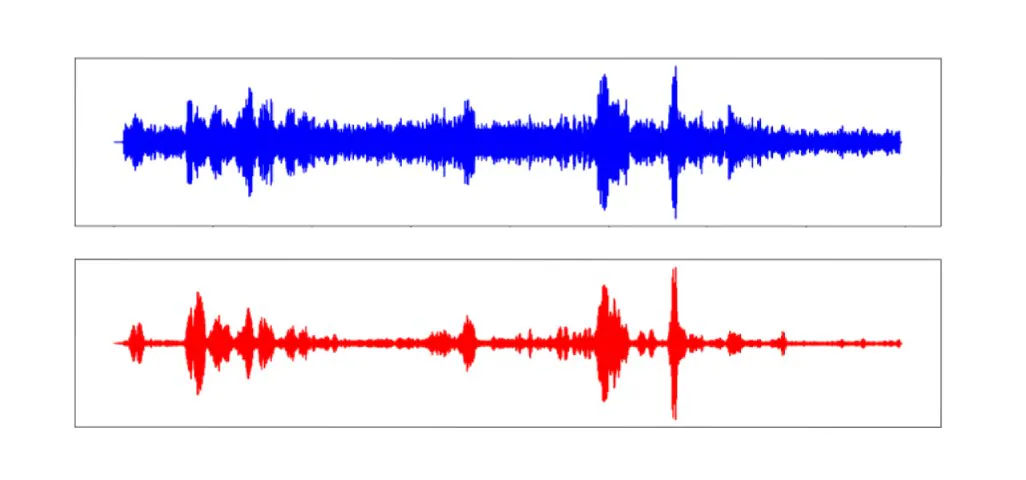
One MP3 file with the prompt read in the cloned voice. Both sample clips are mono at 24 kHz, the sampling rate Coqui lists for XTTS-v2, and each short prompt came back as just over five seconds of speech.
Recommended settings
Use at least 6 seconds of clean speech with no music or second voice. Temperature controls sampling: lower values make repeated runs sound more alike, higher values let them vary more. Start at the 0.75 default.
Limitations
XTTS-v2 copies emotion and speaking style from the reference along with the voice, so the mood and pace of your recording carry into the output. Only the 17 languages in the list are available.
Safety & compliance
Coqui releases XTTS-v2 under the Coqui Public Model License, which allows only non-commercial use of the model and of the audio it produces. Clone a voice only with the consent of the person it belongs to.
API quick start
Run voice-clone with a single API call.
{
  "prompt": "Welcome to Wiro AI! How can we assist you…",
  "inputAudioUrl": "https://your-cdn.com/input.mp3",
  "temp": 0.75,
  "language": "en"
}
curl -X POST "https://api.wiro.ai/v1/Run/wiro/voice-clone" \
-H "Content-Type: application/json" \
-H "x-api-key: YOUR_WIRO_API_KEY" \
--data-binary @- <<'JSON'
{
"prompt": "Welcome to Wiro AI! How can we assist you…",
"inputAudioUrl": "https://your-cdn.com/input.mp3",
"temp": 0.75,
"language": "en"
}
JSONOther models you might like
Explore similar audio & speech models.