Try Kling V4 Video Generator from Kling-AI →
Models
Agents
Workflows
Studio
PricingBlogDocs
ExploreDiscover models by categoryBrowse All ModelsBrowse the complete catalogSee FavoritesSign in to view saved models
Generative Media AgentCreate and edit media by chattingWorkflow AgentBuild visual workflows with Agent
OverviewThe platform at a glanceLearnSkills, knowledge, guardrailsAnatomyWhat makes agents reasonBuild Your AgentPick skills, set tier, deploy
Pre-built AgentsBrowse the catalog
Agent Usecases
Ad Campaign ManagerApp Event ManagerApp Review RepliesBarber BookingCustomer Win-BackEcommerce ListingsRestaurant Reviews
Sign InStart Building

Task History

Click to see output list

No tasks yet

Go to Models
Discover AI models

Search the full model catalog.

Discover and compare production-ready models. Filter by modality, provider, pricing, and production fit.
556 models0 active filters

Wiro AI

Utilities

Video Generation

Text to VideoImage to VideoVideo to Video

Image Generation

Text to ImageImage to ImageImage EditingImage to Text

Audio & Speech

Text to SpeechSpeech to TextSpeech to SpeechVoice Clone

Realtime Stream

Realtime Conversation

Music Generation

Music Generation

3D Generation

LLM & Chat

LLM

Partners

Need help choosing?

Compare models by capability, cost, and provider fit.

Showing 441–460 of 556 models
text-to-image-flux - AI model cover image

text-to-image-flux

wiro

Renders a text prompt with the FLUX.1 checkpoint you pick, such as FLUX.1 [dev], [schnell] or Krea [dev], or with one of your private FLUX.1 fine-tunes.

Text to Image
Run
FLUX.1-dev - AI model cover image

FLUX.1-dev

black-forest-labs

FLUX.1 Dev is Black Forest Labs' 12B open-weight text-to-image model, distilled from FLUX.1 [pro]. It can spell short text inside the image, like the words on a sign or a label.

Text to Image
Run
remove-background - AI model cover image

remove-background

wiro

Removes the background from photos and returns each subject as a PNG cutout with transparency. One run takes up to 30 images.

Image to Image
Run

vgen

wiro

Sets a still image in motion, following a text prompt for what should move. The model is I2VGen-XL from Alibaba's Tongyi Lab, with adjustable frame rate and output size.

Image to Image
Run

live-portrait

wiro

Make your portrait alive! It is a tool that turns your portrait into a video using a provided reference video.

Video to Video
Run

t2v_turbo

wiro

It generates a video from the given prompt.

Text to Video
Run
ic-light-background - AI model cover image

ic-light-background

wiro

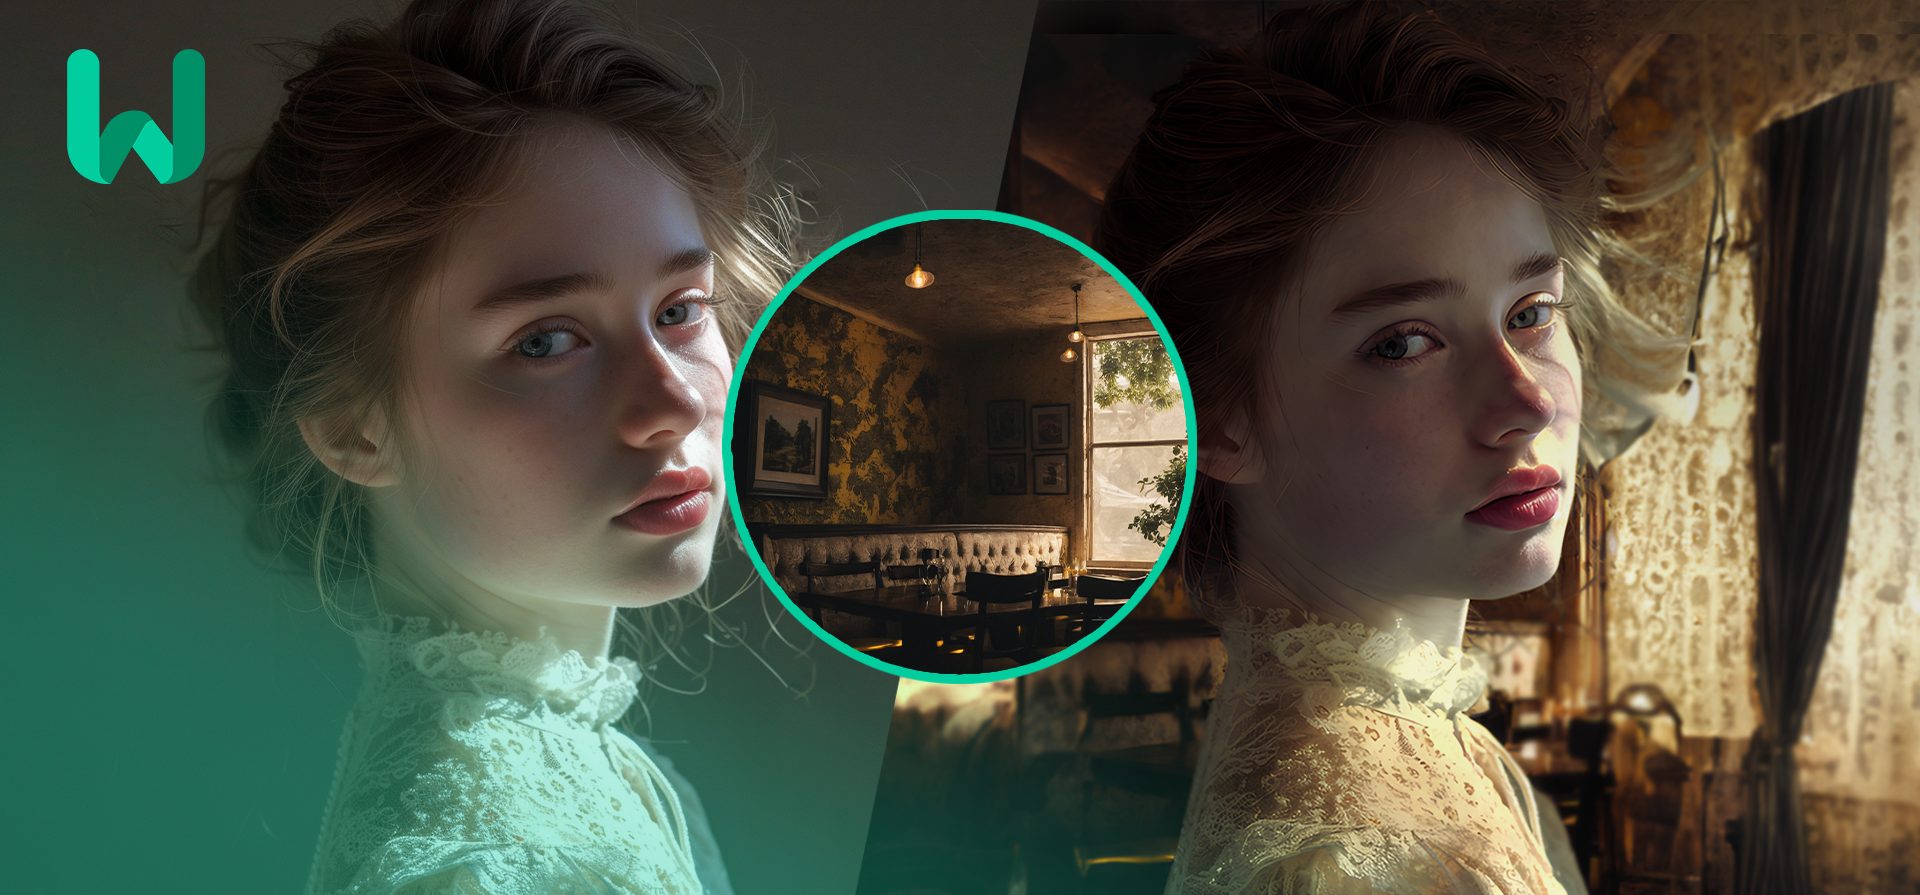
Places the subject of one photo onto a background image you choose and relights the subject to match the new scene, using IC-Light's background-conditioned model.

Image to Image
Run
ic-light - AI model cover image

ic-light

wiro

More Lighting! IC-Light is used to manipulate the illumination of images using a text-conditioned model.

Image to Image
Run
stable-diffusion-with-llm - AI model cover image

stable-diffusion-with-llm

wiro

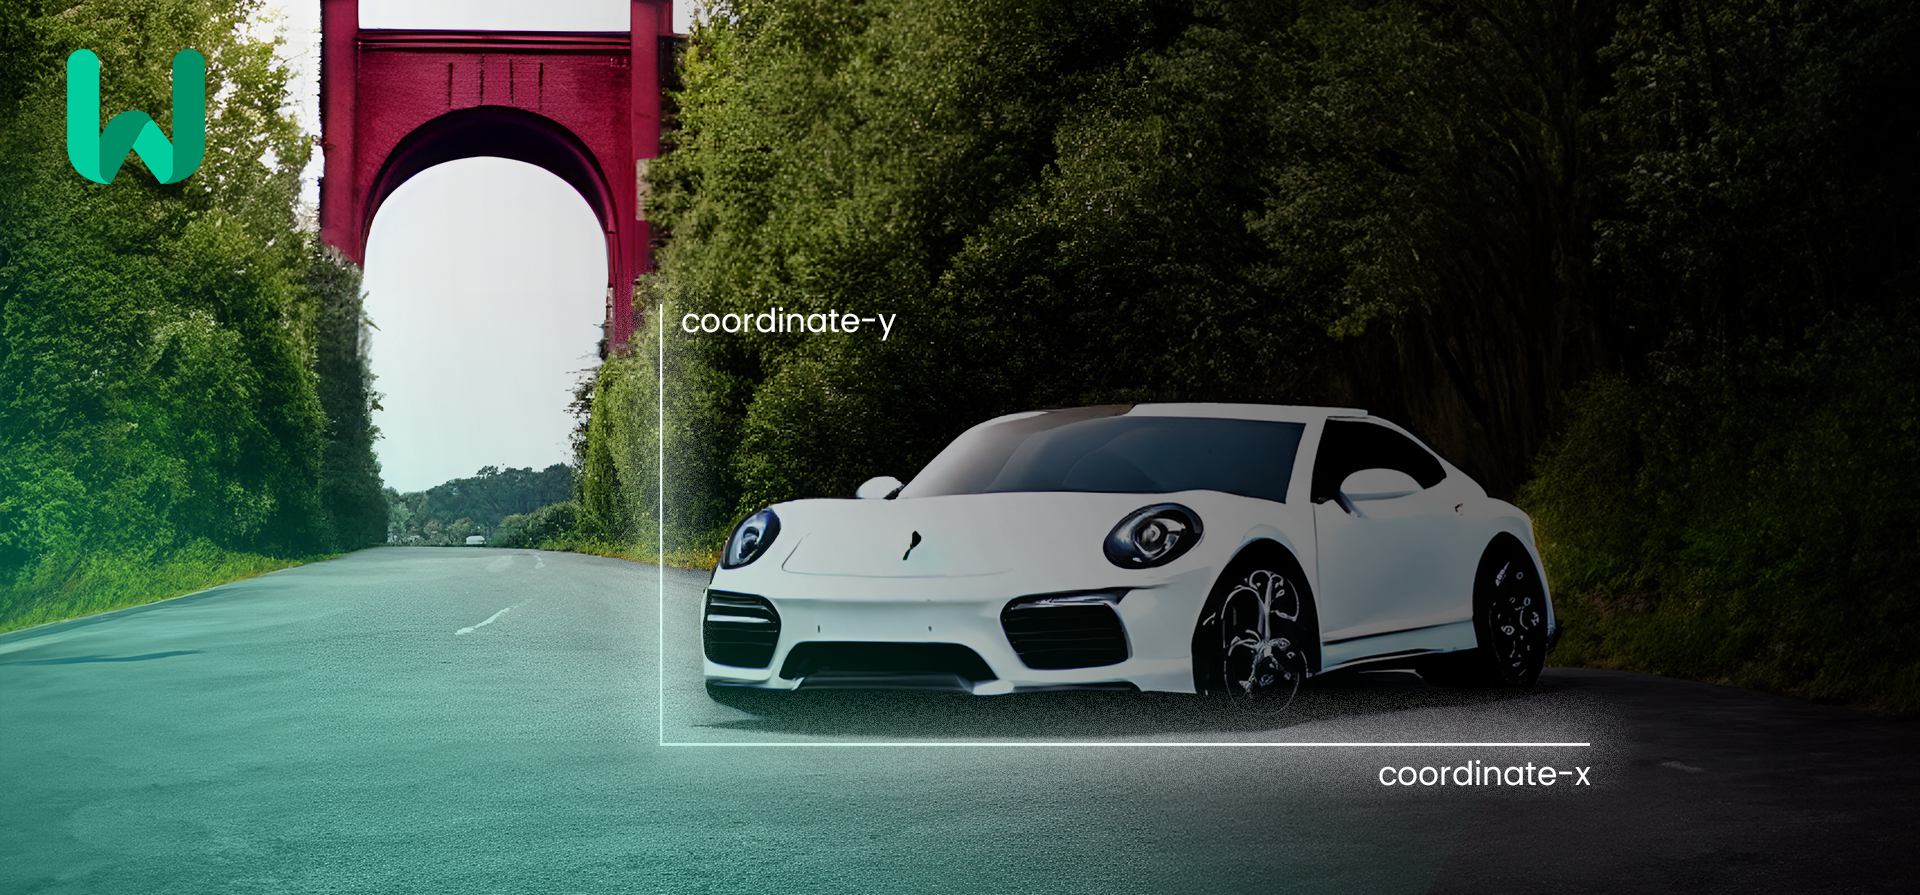
An image generator that takes its layout from you: captioned boxes drawn on a canvas plus a background prompt. LMD+, from the LLM-grounded Diffusion paper, keeps each object inside its box.

Text to Image
Run
hair-fast-gan - AI model cover image

hair-fast-gan

wiro

hair-fast-gan applies the hairstyle and hair color to the input image.

Image to Image
Run
image-restoration - AI model cover image

image-restoration

wiro

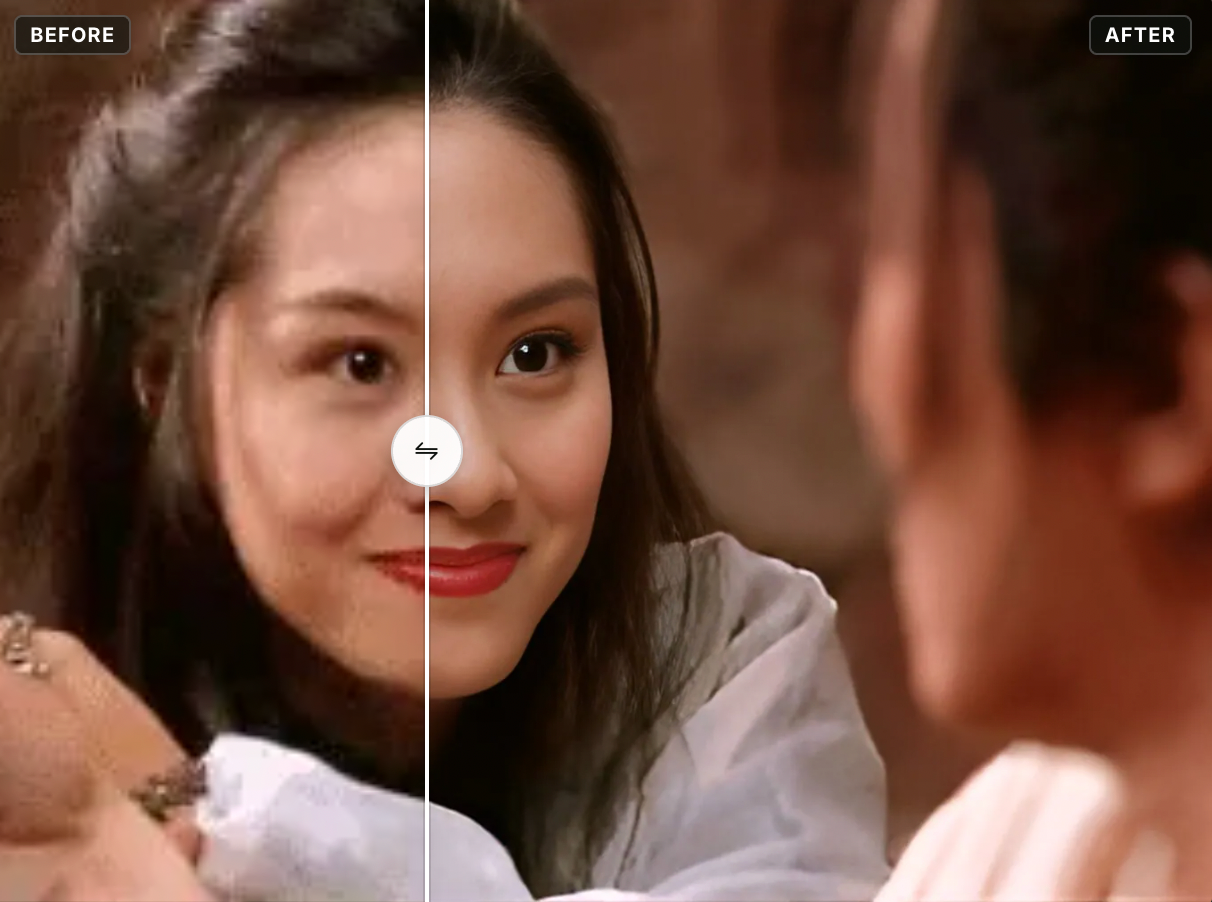
Restores blurry, low-resolution photos: CodeFormer rebuilds the face nearest the center and Real-ESRGAN enlarges the whole frame up to 10 times.

Image to Image
Run

ani-portrait-audio2video

wiro

It creates a video by combining the input image with the movements of a person in a video and adding the audio from the input audio.

Audio To Video
Run

ani-portrait-pose2video

wiro

It creates a video by incorporating the movements and audio of a person from a given video into the input image.

Image to Video
Run

3D

wiro

Transform your 2D object into 3D.

Image to Video
Run
voice-clone - AI model cover image

voice-clone

wiro

Reads text aloud in the voice of a short reference clip. Built on Coqui's XTTS-v2, it needs about six seconds of speech, and the text can be in any of 17 languages, whatever language the clip is in.

Speech to Speech
Run
whisper-medium - AI model cover image

whisper-medium

openai

OpenAI Whisper Medium transcribes speech to text with timestamps and optional speaker diarization. Works across many languages and noisy audio.

Speech to Textspeech-to-textwhisper
Run
Unlimited-OCR - AI model cover image

Unlimited-OCR

baidu

Unlimited OCR by Baidu parses scanned pages and long PDFs in one pass and returns structured, readable text for search, RAG, and document workflows.

Fast Inferenceimage-text-to-textsafetensors
Run
ERNIE-Image-Turbo - AI model cover image

ERNIE-Image-Turbo

baidu

The distilled 8-step checkpoint of Baidu's ERNIE-Image text-to-image model. Baidu says it keeps the parent's text rendering and layout handling, and it includes a prompt enhancer.

Text to Imagetext-to-imagediffusers
Run
ERNIE-Image - AI model cover image

ERNIE-Image

baidu

Baidu's 8B open-weight text-to-image model, the 50-step SFT release of ERNIE-Image. Its strength is images that carry a lot of text, such as posters, infographics and multi-panel comics.

Text to Imagetext-to-imagediffusers
Run
dots.ocr-1.5 - AI model cover image

dots.ocr-1.5

kristaller486

A 3B OCR model from rednote-hilab that turns PDFs and images into Markdown with HTML tables and LaTeX formulas, plus a labeled box for every block. Its makers designed it to read almost any human script.

Fast Inferenceimage-text-to-textsafetensors
Run
Showing 441–460 of 556 models
  • 1
  • …
  • 21
  • 22
  • 23
  • 24
  • 25
  • …
  • 28

Discover, test, and run AI models, build workflows and agents with one unified API.

All systems operational
WiroModelsAgentsPricingAboutBlogCareersContactPartnerChangelogStatusFAQ
CategoriesText to ImageImage to ImageImage EditingImage to TextText to VideoImage to VideoVideo to VideoText to SpeechSpeech to TextSpeech to SpeechVoice CloneRealtime ConversationMusic GenerationLLMUtilities
ModelsNano Banana 2GPT Image 2.5Seedream V5 ProSeedance 2.5Veo 3.1Kling V3FLUX 3FLUX.2 ProWan 3.0 PrimeGrok Imagine 1.5
PartnersGoogleOpenAIByteDanceBlack Forest LabsKling AIQwenAlibabaxAIMiniMaxElevenLabs
Getting StartedIntroductionAuthenticationProjectsCode ExamplesWiro MCP ServerSelf-Hosted MCPn8n IntegrationLLMs.txt
API ReferenceModelsRun a ModelModel ParametersTasksLLM & Chat StreamingWebSocketRealtime VoiceFiles
© 2026 Wiro AI. All rights reserved.
PrivacyTermsData Deletion