Filters0 active

Wiro AI

Video Generation

Image Generation

Audio & Speech

Realtime Stream

Music Generation

3D Generation

LLM & Chat

Partners

Try GPT Image 2.6 Flare by OpenAI from OpenAI →
Models
Agents
Workflows
Studio
PricingBlogDocs
ExploreDiscover models by categoryDiscoverModels and effects built by WiroBrowse All ModelsBrowse the complete catalogSee FavoritesSign in to view saved models
Generative Media AgentCreate and edit media by chattingWorkflow AgentBuild visual workflows with Agent
OverviewThe platform at a glanceLearnSkills, knowledge, guardrailsAnatomyWhat makes agents reasonBuild Your AgentPick connectors and skills, set tier, deploy
Pre-built AgentsBrowse the catalog
Agent Usecases
Ad Campaign ManagerApp Event ManagerApp Review RepliesBarber BookingCustomer Win-BackEcommerce ListingsRestaurant Reviews
Sign InStart Building
Discover AI models

Search the full model catalog.

Discover and compare production-ready models. Filter by modality, provider, pricing, and production fit.

AI Models and Tools
560 models0 active filters

Wiro AI

Utilities

Video Generation

Text to VideoImage to VideoVideo to Video

Image Generation

Text to ImageImage to ImageImage EditingImage to Text

Audio & Speech

Text to SpeechSpeech to TextSpeech to SpeechVoice Clone

Realtime Stream

Realtime Conversation

Music Generation

Music Generation

3D Generation

LLM & Chat

LLM

Partners

Need help choosing?

Compare models by capability, cost, and provider fit.

Showing 221–240 of 560 models
rag-chat-youtube - AI model cover image

rag-chat-youtube

wiro

Ask questions about a YouTube video and get answers drawn from its captions, using a chat model you pick. Videos without captions are transcribed from their audio first.

Chatconversational text-generation-inference
Run

SkyReels-V1

wiro

SkyReels V1 is the first and most advanced open-source human-centric video model.

Image to Video
Run
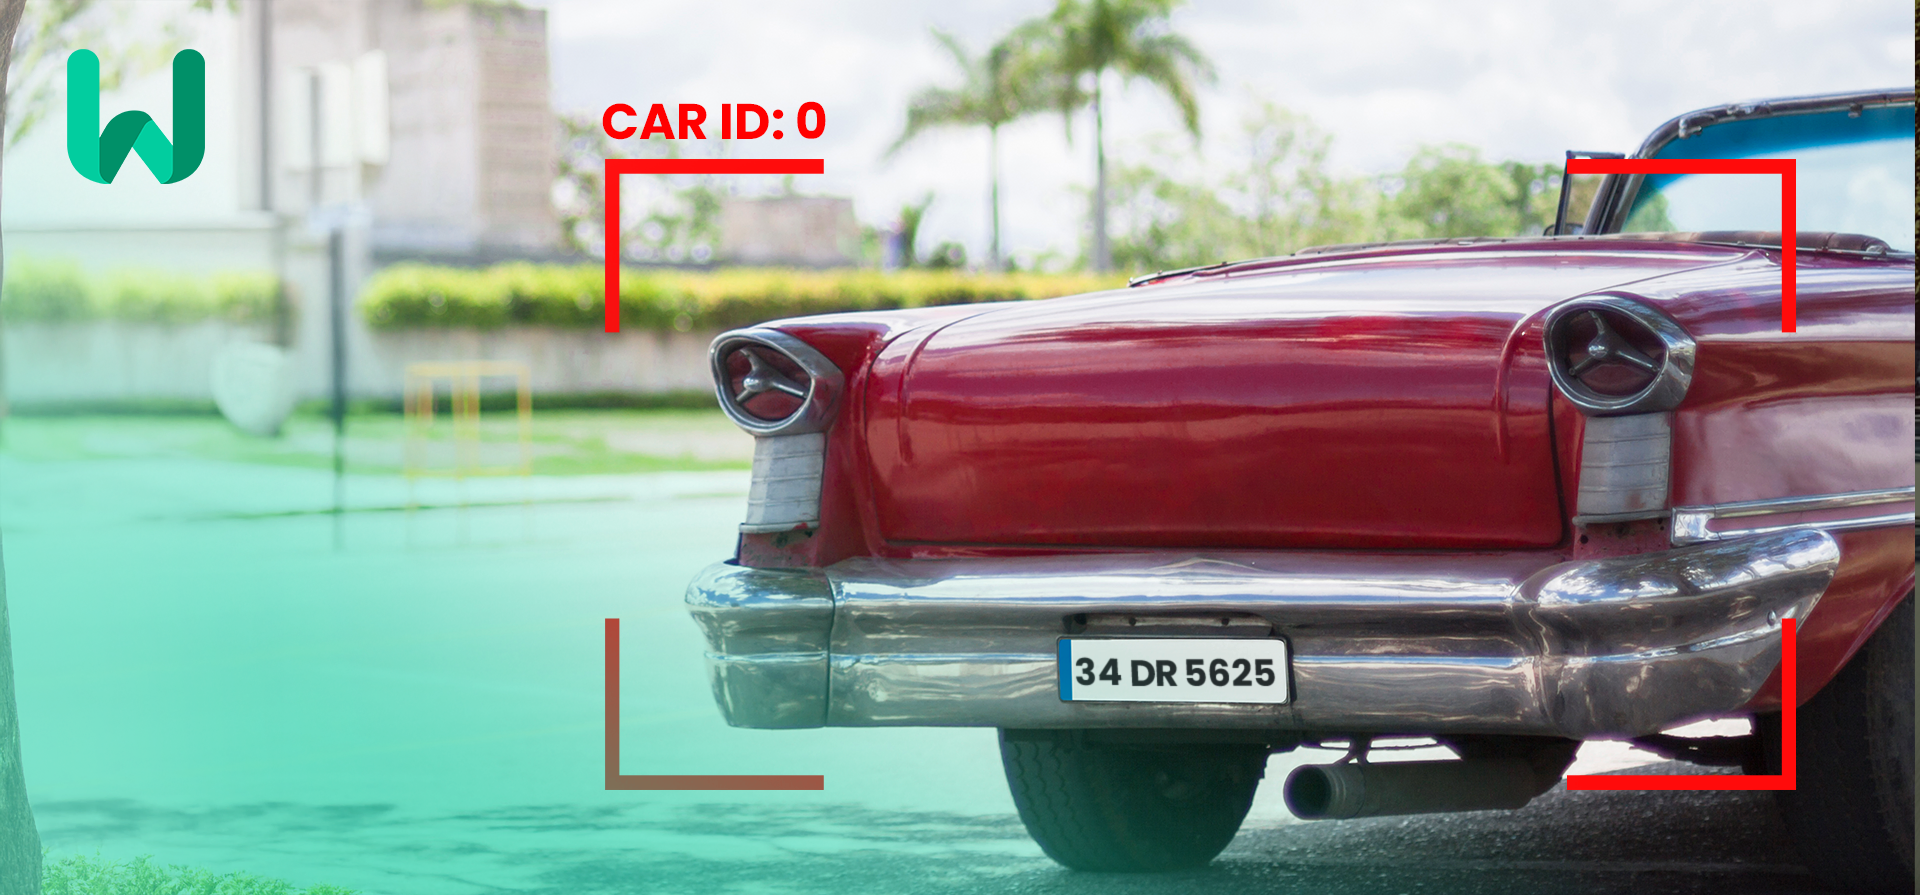
license-plate-recognition-image - AI model cover image

license-plate-recognition-image

wiro

Reads Turkish license plates in a photo and returns them as text, along with a copy of the image where each car is numbered and each plate is boxed.

Image to Image
Run
AI-Job-Description-Generator - AI model cover image

AI-Job-Description-Generator

wiro

Turns a few lines of hiring notes into a formatted job posting in English or Turkish, in one of five tones. CVs or an older posting can be attached as extra context.

Human Resourcescv analyzerresume evaluation
Run

memo

wiro

MEMO animates a single portrait so it talks or sings along to an audio clip, keeping the face consistent over long videos and matching the expression to the emotion in the voice.

Talking Headlip synctalking head
Run
AI-Resume-CV-Evaluator-JobDesc - AI model cover image

AI-Resume-CV-Evaluator-JobDesc

wiro

Scores each uploaded CV against a job description you paste in. Each score comes with a written review of qualifications, experience, skills and job fit, and the detailed mode adds the parsed profile.

Human Resourcescv analyzerresume evaluation
Run
AI-Resume-CV-Parser - AI model cover image

AI-Resume-CV-Parser

wiro

Reads a batch of CVs and returns one structured record per candidate (contact details, skills, certifications, job history and education) in a combined JSON or CSV file, plus one file per CV.

Human Resourcescv analyzerresume evaluation
Run
Llama3-Med42-8B - AI model cover image

Llama3-Med42-8B

m42-health

An 8B clinical chat model from M42, fine-tuned from Llama 3 8B Instruct to answer the medical questions that general-purpose assistants are often tuned to avoid.

Chattext generationtransformers
Run
SmolLM2-1.7B-Instruct - AI model cover image

SmolLM2-1.7B-Instruct

HuggingFaceTB

A 1.7B-parameter English chat model from Hugging Face's SmolLM2 family, built small enough to run on-device and tuned with SFT and DPO for instruction following and function calling.

Chattext generationtransformers
Run

mmaudio

wiro

Generate synchronized audio for videos using AI. Enhance video content with matching sound effects or create custom audio from text descriptions.

Video to Video
Run
rag-chat - AI model cover image

rag-chat

wiro

Answers questions from files you upload, such as PDF, Word, PowerPoint or CSV. The chat model you choose writes each answer from the passages that best match the question.

Chatconversational text-generation-inference
Run
text-to-image-flux-lora - AI model cover image

text-to-image-flux-lora

wiro

Generate images from a text prompt with a FLUX.1 base model and a LoRA of your choice: a public style listed on Wiro, one of your private LoRAs, or a .safetensors file by URL.

Text to Image
Run

ask-video

wiro

Writes a detailed English description of a video clip, guided by your prompt. Built on THUDM's CogVLM2-Llama3-Caption, the model that captioned training data for CogVideoX.

Video to Textvideo-text-to-texttransformers
Run

cogvlm2-llama3-caption

THUDM

Writes one detailed English paragraph describing a video clip from start to finish. THUDM built it to caption training data for its CogVideoX text-to-video model.

Video to Textvideo-text-to-texttransformers
Run
bark - AI model cover image

bark

suno-ai

Suno's Bark reads text aloud in 13 languages with one of 130 voice presets. Cues such as [laughs], [sighs] or lyrics wrapped in ♪ add nonverbal sounds and sung lines.

Text to Speechsuno-aibark
Run

BiRefNet

ZhengPeng7

Cuts the main subject out of a photo and returns it on a transparent background at the original size. BiRefNet is a high-resolution segmentation model that uses gradient maps to keep fine edges.

Image to Imageimage segmentationbirefnet
Run
FLUX.1-schnell - AI model cover image

FLUX.1-schnell

black-forest-labs

Turns a text prompt into an image in 1 to 4 sampling steps. Black Forest Labs released it under Apache 2.0, so the model and its images can be used commercially.

Text to Image
Run
remove-background - AI model cover image

remove-background

wiro

Removes the background from photos and returns each subject as a PNG cutout with transparency. One run takes up to 30 images.

Image to Image
Run

vgen

wiro

Sets a still image in motion, following a text prompt for what should move. The model is I2VGen-XL from Alibaba's Tongyi Lab, with adjustable frame rate and output size.

Image to Image
Run
hair-fast-gan - AI model cover image

hair-fast-gan

wiro

hair-fast-gan applies the hairstyle and hair color to the input image.

Image to Image
Run
Showing 221–240 of 560 models
  • 1
  • …
  • 10
  • 11
  • 12
  • 13
  • 14
  • …
  • 28

Discover, test, and run AI models, build workflows and agents with one unified API.

All systems operational
WiroModelsAgentsPricingAboutBlogCareersContactPartnerChangelogStatusFAQ
CategoriesText to ImageImage to ImageImage EditingImage to TextText to VideoImage to VideoVideo to VideoText to SpeechSpeech to TextSpeech to SpeechVoice CloneRealtime ConversationMusic GenerationLLMUtilities
ModelsNano Banana 2GPT Image 2.5Seedream V5 ProSeedance 2.5Veo 3.1Kling V3FLUX 3FLUX.2 ProWan 3.0 PrimeGrok Imagine 1.5
PartnersGoogleOpenAIByteDanceBlack Forest LabsKling AIQwenAlibabaxAIMiniMaxElevenLabs
Getting StartedWiro ModelsWiro EffectsIntroductionAuthenticationProjectsCode ExamplesWiro MCP ServerSelf-Hosted MCPn8n IntegrationLLMs.txt
API ReferenceModelsRun a ModelModel ParametersTasksLLM & Chat StreamingWebSocketRealtime VoiceFiles
© 2026 Wiro AI. All rights reserved.
PrivacyTermsData Deletion