Filters0 active

Wiro AI

Video Generation

Image Generation

Audio & Speech

Realtime Stream

Music Generation

3D Generation

LLM & Chat

Partners

Try GPT Image 2.6 Flare by OpenAI from OpenAI →
Models
Agents
Workflows
Studio
PricingBlogDocs
ExploreDiscover models by categoryDiscoverModels and effects built by WiroBrowse All ModelsBrowse the complete catalogSee FavoritesSign in to view saved models
Generative Media AgentCreate and edit media by chattingWorkflow AgentBuild visual workflows with Agent
OverviewThe platform at a glanceLearnSkills, knowledge, guardrailsAnatomyWhat makes agents reasonBuild Your AgentPick connectors and skills, set tier, deploy
Pre-built AgentsBrowse the catalog
Agent Usecases
Ad Campaign ManagerApp Event ManagerApp Review RepliesBarber BookingCustomer Win-BackEcommerce ListingsRestaurant Reviews
Sign InStart Building
Discover AI models

Search the full model catalog.

Discover and compare production-ready models. Filter by modality, provider, pricing, and production fit.

AI Models and Tools
560 models0 active filters

Wiro AI

Utilities

Video Generation

Text to VideoImage to VideoVideo to Video

Image Generation

Text to ImageImage to ImageImage EditingImage to Text

Audio & Speech

Text to SpeechSpeech to TextSpeech to SpeechVoice Clone

Realtime Stream

Realtime Conversation

Music Generation

Music Generation

3D Generation

LLM & Chat

LLM

Partners

Need help choosing?

Compare models by capability, cost, and provider fit.

Showing 521–540 of 560 models
Llama-3.1-8B-Instruct - AI model cover image

Llama-3.1-8B-Instruct

meta-llama

The 8B instruction-tuned model of Meta's Llama 3.1 collection, for chat and code in eight languages. It was pretrained on roughly 15 trillion tokens, and its knowledge stops at December 2023.

Chattext generationtransformers
Run
Qwen2.5-7B-Instruct - AI model cover image

Qwen2.5-7B-Instruct

Qwen

Qwen2.5's 7B chat model (7.61B parameters) with JSON mode, function calling and up to 32,768 input tokens on Wiro. Qwen reports 75.5 on MATH and 84.8 on HumanEval.

Chattext generationtransformers
Run
chat - AI model cover image

chat

wiro

One set of chat inputs for open-weight models hosted on Wiro, such as Llama, Qwen, Mistral and DeepSeek. Choose the base model on each request and keep separate conversation histories per user and session.

Chatconversational text-generation-inference
Run
wiroai-turkish-llm-8b - AI model cover image

wiroai-turkish-llm-8b

wiro

Wiro AI's 8B Turkish chat model: Llama 3.1 8B Instruct fine-tuned on more than 500,000 Turkish instructions, with a focus on Turkish idioms and local context.

Chatconversationaltext-generation-inference
Run
wiroai-turkish-llm-9b - AI model cover image

wiroai-turkish-llm-9b

wiro

Wiro's Turkish chat model, fine-tuned from Google's Gemma 2 9B on more than 500,000 Turkish instructions to answer in natural Turkish with local and cultural context.

Chatconversational text-generation-inference
Run
face_anonymization - AI model cover image

face_anonymization

wiro

Detects the faces in a photo and covers each one with a blurred oval, leaving the rest of the image untouched. One image in, one PNG out at the original size.

Image to Image
Run
Llama-2-13b-hf - AI model cover image

Llama-2-13b-hf

meta-llama

The pretrained 13B-parameter Llama 2 base model from Meta, with no chat or instruction tuning. It continues the text you give it, for story drafting and pattern completion in English.

LLMtext-generation-inferencetext generation
Run
FLUX.1-dev-fp8-v1.0 - AI model cover image

FLUX.1-dev-fp8-v1.0

AbdallahAlswa80

FP8 checkpoint of Black Forest Labs' 12B FLUX.1 [dev] text-to-image model, stored at one byte per weight instead of two. A run returns up to eight PNG images at up to 2048 pixels per side.

Text to Imagebase model
Run
blip2-flan-t5-xl - AI model cover image

blip2-flan-t5-xl

Salesforce

Answers questions about one image or captions it, using Google's instruction-tuned Flan-T5-XL as the language model inside BLIP-2. Only the answer text comes back.

Image to Textimage-text-to-texttransformers
Run
blip-image-captioning-large - AI model cover image

blip-image-captioning-large

Salesforce

The larger BLIP captioning checkpoint from Salesforce, with a ViT-L image encoder and trained on COCO. It takes one image plus an optional opening phrase and returns a short English caption.

Image to Textimage-to-texttransformers
Run
blip-image-captioning-base - AI model cover image

blip-image-captioning-base

Salesforce

BLIP captioning checkpoint from Salesforce with a ViT-B image encoder, trained on COCO. It writes a short English caption for an image and can continue an opening phrase you give it.

Image to Textimage-to-texttransformers
Run
img-to-img-flux - AI model cover image

img-to-img-flux

wiro

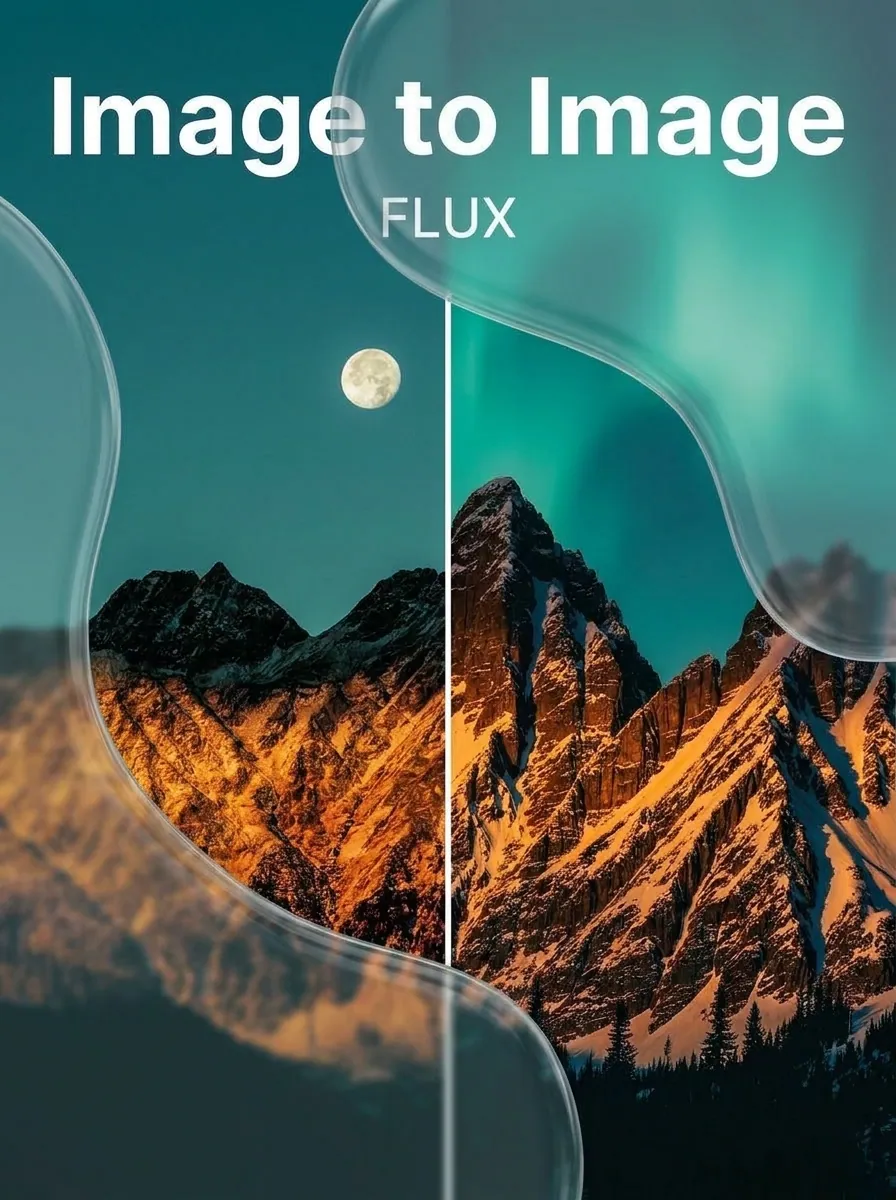
Repaints an existing image from a text prompt with a FLUX.1 checkpoint you pick. A strength setting decides how much of the source survives, from a light restyle to a near full redraw.

Image to Image
Run
text-to-image-flux-lora - AI model cover image

text-to-image-flux-lora

wiro

Generate images from a text prompt with a FLUX.1 base model and a LoRA of your choice: a public style listed on Wiro, one of your private LoRAs, or a .safetensors file by URL.

Text to Image
Run
FLUX.1-Fill-dev - AI model cover image

FLUX.1-Fill-dev

black-forest-labs

Inpainting and outpainting model from Black Forest Labs. Upload a photo and a mask, describe what belongs in the masked area, and only that area is repainted to fit the rest of the image.

Image to Imagediffusersfluxfillpipeline
Run

ask-video

wiro

Writes a detailed English description of a video clip, guided by your prompt. Built on THUDM's CogVLM2-Llama3-Caption, the model that captioned training data for CogVideoX.

Video to Textvideo-text-to-texttransformers
Run

cogvlm2-llama3-caption

THUDM

Writes one detailed English paragraph describing a video clip from start to finish. THUDM built it to caption training data for its CogVideoX text-to-video model.

Video to Textvideo-text-to-texttransformers
Run
Llama-2-7b-chat-hf - AI model cover image

Llama-2-7b-chat-hf

meta-llama

Meta's 7B Llama 2 chat model, aligned for English dialogue with supervised fine-tuning and RLHF. Text in, text out, with a 4k-token context window.

Chattext-generation-inferencellama2-chat
Run

BiRefNet

ZhengPeng7

Cuts the main subject out of a photo and returns it on a transparent background at the original size. BiRefNet is a high-resolution segmentation model that uses gradient maps to keep fine edges.

Image to Imageimage segmentationbirefnet
Run
text-to-image-sana - AI model cover image

text-to-image-sana

wiro

A Wiro app that runs NVIDIA's 1.6B Sana text-to-image model with a base model picker, switching between four checkpoints that target 1024px, 2K and 4K output.

Text to Image
Run
text-to-image-flux - AI model cover image

text-to-image-flux

wiro

Renders a text prompt with the FLUX.1 checkpoint you pick, such as FLUX.1 [dev], [schnell] or Krea [dev], or with one of your private FLUX.1 fine-tunes.

Text to Image
Run
Showing 521–540 of 560 models
  • 1
  • …
  • 23
  • 24
  • 25
  • 26
  • 27
  • 28

Discover, test, and run AI models, build workflows and agents with one unified API.

All systems operational
WiroModelsAgentsPricingAboutBlogCareersContactPartnerChangelogStatusFAQ
CategoriesText to ImageImage to ImageImage EditingImage to TextText to VideoImage to VideoVideo to VideoText to SpeechSpeech to TextSpeech to SpeechVoice CloneRealtime ConversationMusic GenerationLLMUtilities
ModelsNano Banana 2GPT Image 2.5Seedream V5 ProSeedance 2.5Veo 3.1Kling V3FLUX 3FLUX.2 ProWan 3.0 PrimeGrok Imagine 1.5
PartnersGoogleOpenAIByteDanceBlack Forest LabsKling AIQwenAlibabaxAIMiniMaxElevenLabs
Getting StartedWiro ModelsWiro EffectsIntroductionAuthenticationProjectsCode ExamplesWiro MCP ServerSelf-Hosted MCPn8n IntegrationLLMs.txt
API ReferenceModelsRun a ModelModel ParametersTasksLLM & Chat StreamingWebSocketRealtime VoiceFiles
© 2026 Wiro AI. All rights reserved.
PrivacyTermsData Deletion