LongCat-Image
Meituan's 6B-parameter text-to-image model for Chinese and English prompts. Quoted words go through character-level encoding, so headlines and signs come out legible.


Overview
LongCat-Image is the text-to-image model in Meituan LongCat's open-weight image release, built for prompts in Chinese and English. Its core diffusion model has 6B parameters and reads prompts through a Qwen2.5-VL encoder. Meituan's comparison tables set it against open models several times larger, such as the 20B Qwen-Image and the 80B HunyuanImage-3.0, and on GenEval it scores 0.87, level with Qwen-Image.
Words you put inside quotation marks are encoded one character at a time. That is how it spells out headlines and signs. Meituan measured this with ChineseWord, its own test with one prompt for each of the 8,105 characters in China's General Standard Chinese Characters Table, and reports a score of 90.7. On T2I-CoreBench, the team says LongCat-Image placed second among open-source models, behind the 32B-parameter FLUX.2 [dev].
What you can build
- Posters and packaging mockups with Chinese or English headlines
- Shop fronts and street signs with lettering set into photographic scenes
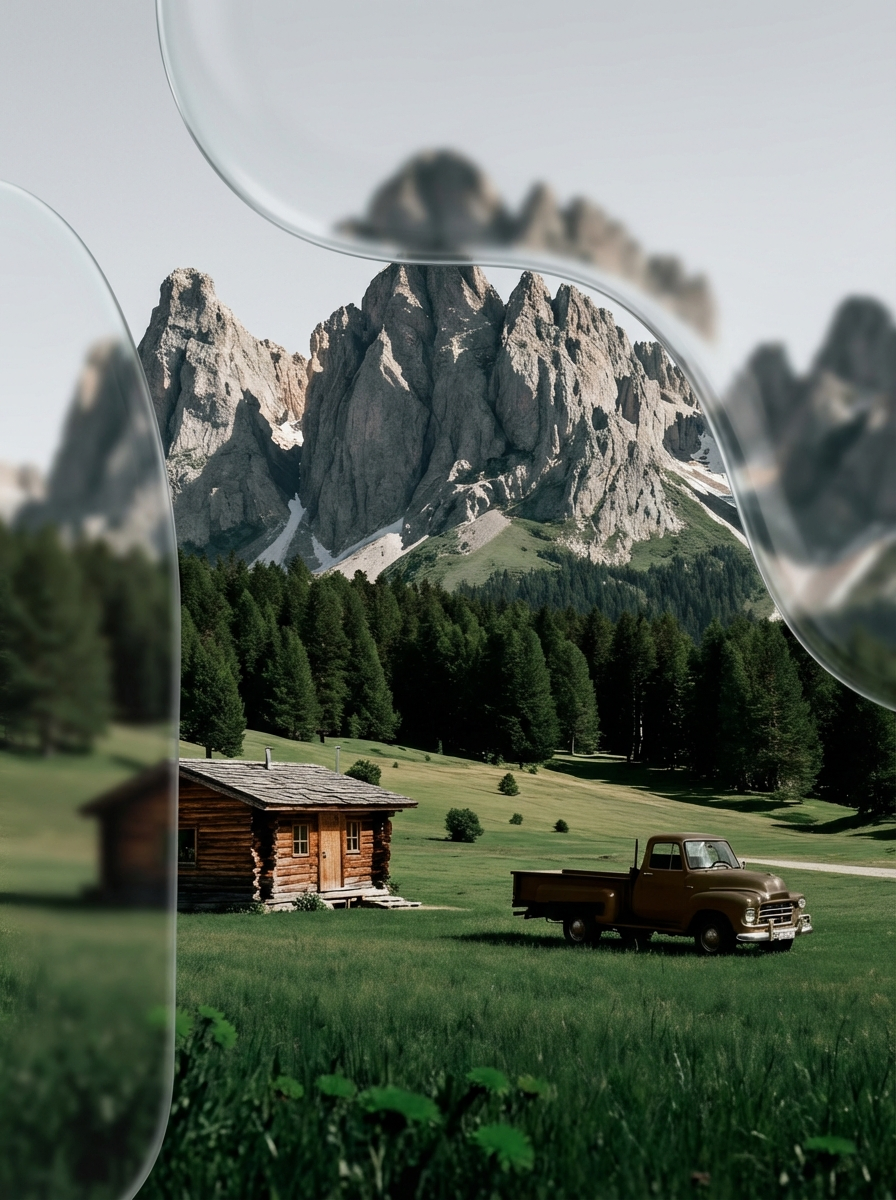
- Landscape and travel imagery, like the samples of a log cabin under jagged alpine peaks and a river winding between karst hills
- Surreal still lifes, for example a glowing jellyfish perched on a melting ice block strewn with gold coins
- Fantasy portraits such as the sample elf in a dress of leaves standing in a misty forest
Inputs
The prompt is the only required field. Wrap any lettering that should appear in the picture in quotes: straight single or double quotes work, and so do Chinese curly quotes.
The aspect ratio menu offers Default plus six fixed sizes: 1024x1024 and 512x512 squares, 576x1024 (9:16), 1024x576 (16:9), 1024x768 (4:3) and 768x1024 (3:4). Under advanced settings you can set inference steps from 1 to 50 (default 28), guidance scale from 1 to 20 (default 4.5), between 1 and 8 images per run, and a seed.
Outputs
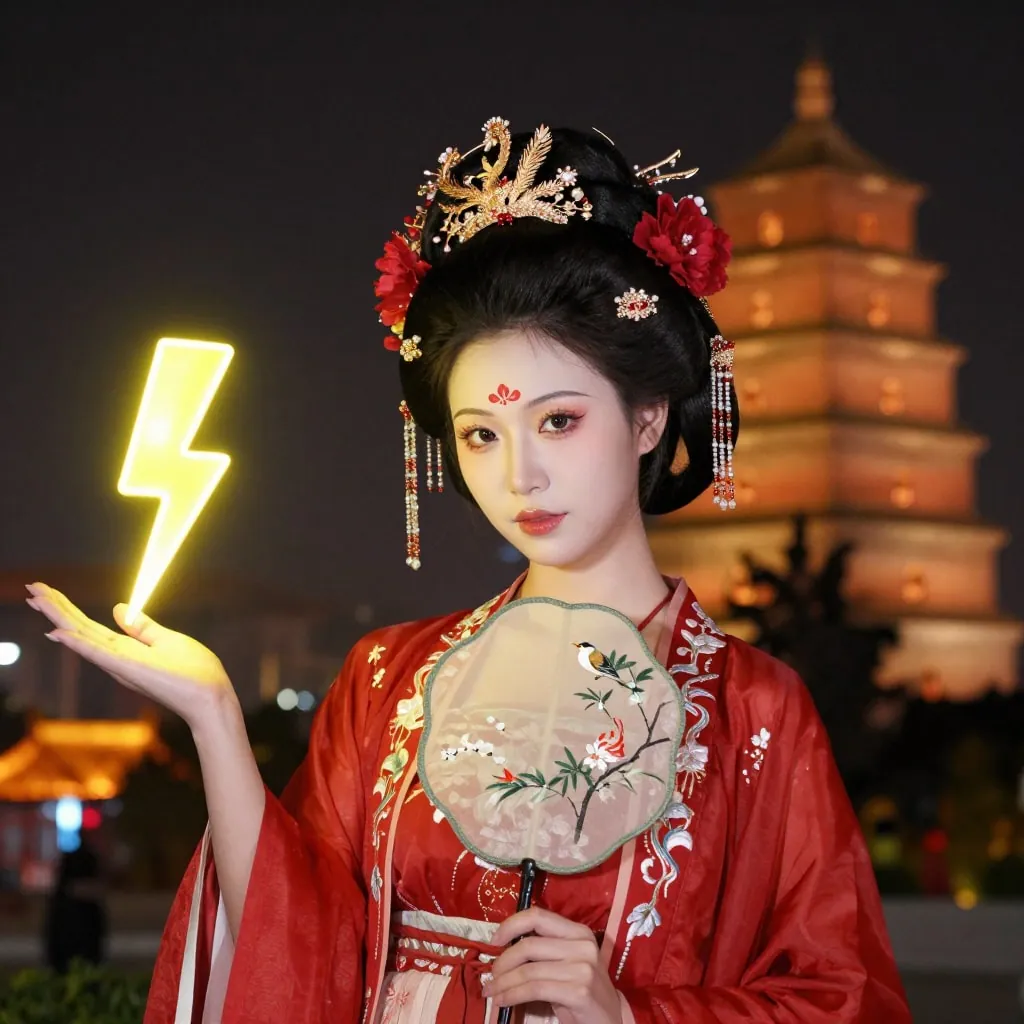
Still images, one to eight per request. The sample outputs on this page are 1024x1024 squares and 768x1344 portraits.
Recommended settings
- To get closer to Meituan's published example, raise steps to 50 and lower guidance to 4.0.
- Put every word you want printed in quotes, spelled exactly as it should appear.
- Write long, specific prompts. Meituan's own example is a full paragraph about one woman, her clothes, the light and the framing, and its model card says refining prompts with a stronger language model helps.
Limitations
- Text rendering depends on the quotes. Without them the character-level path is skipped, and Meituan warns that text quality drops severely.
- Meituan's technical report says the model handles single characters best and becomes noticeably less stable when it has to render longer runs of characters, which the team attributes to limited real-world text in its training data.
- In Meituan's human evaluation, Seedream 4.0 rated higher on alignment (4.25 against 3.99) and on plausibility (3.76 against 3.48). LongCat-Image had the top realism score in that study, 3.60.
Safety & compliance
The weights are released under the Apache 2.0 license. Meituan says the model was not designed or fully evaluated for every downstream application, and it asks developers to run their own checks before putting it into a sensitive or high-risk product. Following the data protection and privacy laws that apply to your product is up to you.
API quick start
Run LongCat-Image with a single API call.
{
  "prompt": "An ethereal female elf with long platinum…",
  "aspectRatio": "Default",
  "steps": 28,
  "scale": 4.5
}
curl -X POST "https://api.wiro.ai/v1/Run/meituan-longcat/longcat-image" \
-H "Content-Type: application/json" \
-H "x-api-key: YOUR_WIRO_API_KEY" \
--data-binary @- <<'JSON'
{
"prompt": "An ethereal female elf with long platinum…",
"aspectRatio": "Default",
"steps": 28,
"scale": 4.5
}
JSONOther models you might like
Explore similar image generation models.