Sana 1600M 1024px
Half-precision (FP16) weights for Sana 1.6B at 1024px. NVIDIA's model pairs a linear diffusion transformer with a Gemma 2 text encoder and a 32x compression autoencoder.
Overview
Sana 1600M 1024px is the half-precision (FP16) build of Sana 1.6B from NVIDIA, in diffusers format under Efficient-Large-Model. The repository dates from late November 2024, before NVIDIA added the BF16 checkpoints in December.
The card describes a Linear Diffusion Transformer of 1648M parameters. Sana replaces the usual attention layers with linear attention and works in the latent space of DC-AE, which compresses images 32 times where the Sana paper puts traditional autoencoders at 8 times. Gemma2-2B-IT, kept frozen, reads the prompt.
Choosing a variant: NVIDIA's model zoo tags Sana 1600M 1024px BF16 as multi-language and leaves this checkpoint untagged, so send Chinese or emoji prompts to the BF16 build. This page suits English prompts at 1024px. The two builds share architecture and size but come from separate releases with different weights. Sana 1600M 2Kpx BF16 and Sana 1600M 4Kpx BF16 cover bigger canvases. Sana Text to Image switches between all four checkpoints with a single field.
What you can build
- Blog headers, thumbnails and social images from English prompts, sized around 1024 pixels per side.
- Concept sketches for game characters, buildings and creatures.
Inputs
Both text fields are required: your prompt, and a negative field that already holds "bad, ugly, low quality". Advanced settings expose a step count from 1 to 500 (25 by default), a guidance scale from 1 to 20 (3.5 by default), 1 to 8 images per run, a seed, and output dimensions that start at 1024 and go as high as 4096 pixels on each side.
Outputs
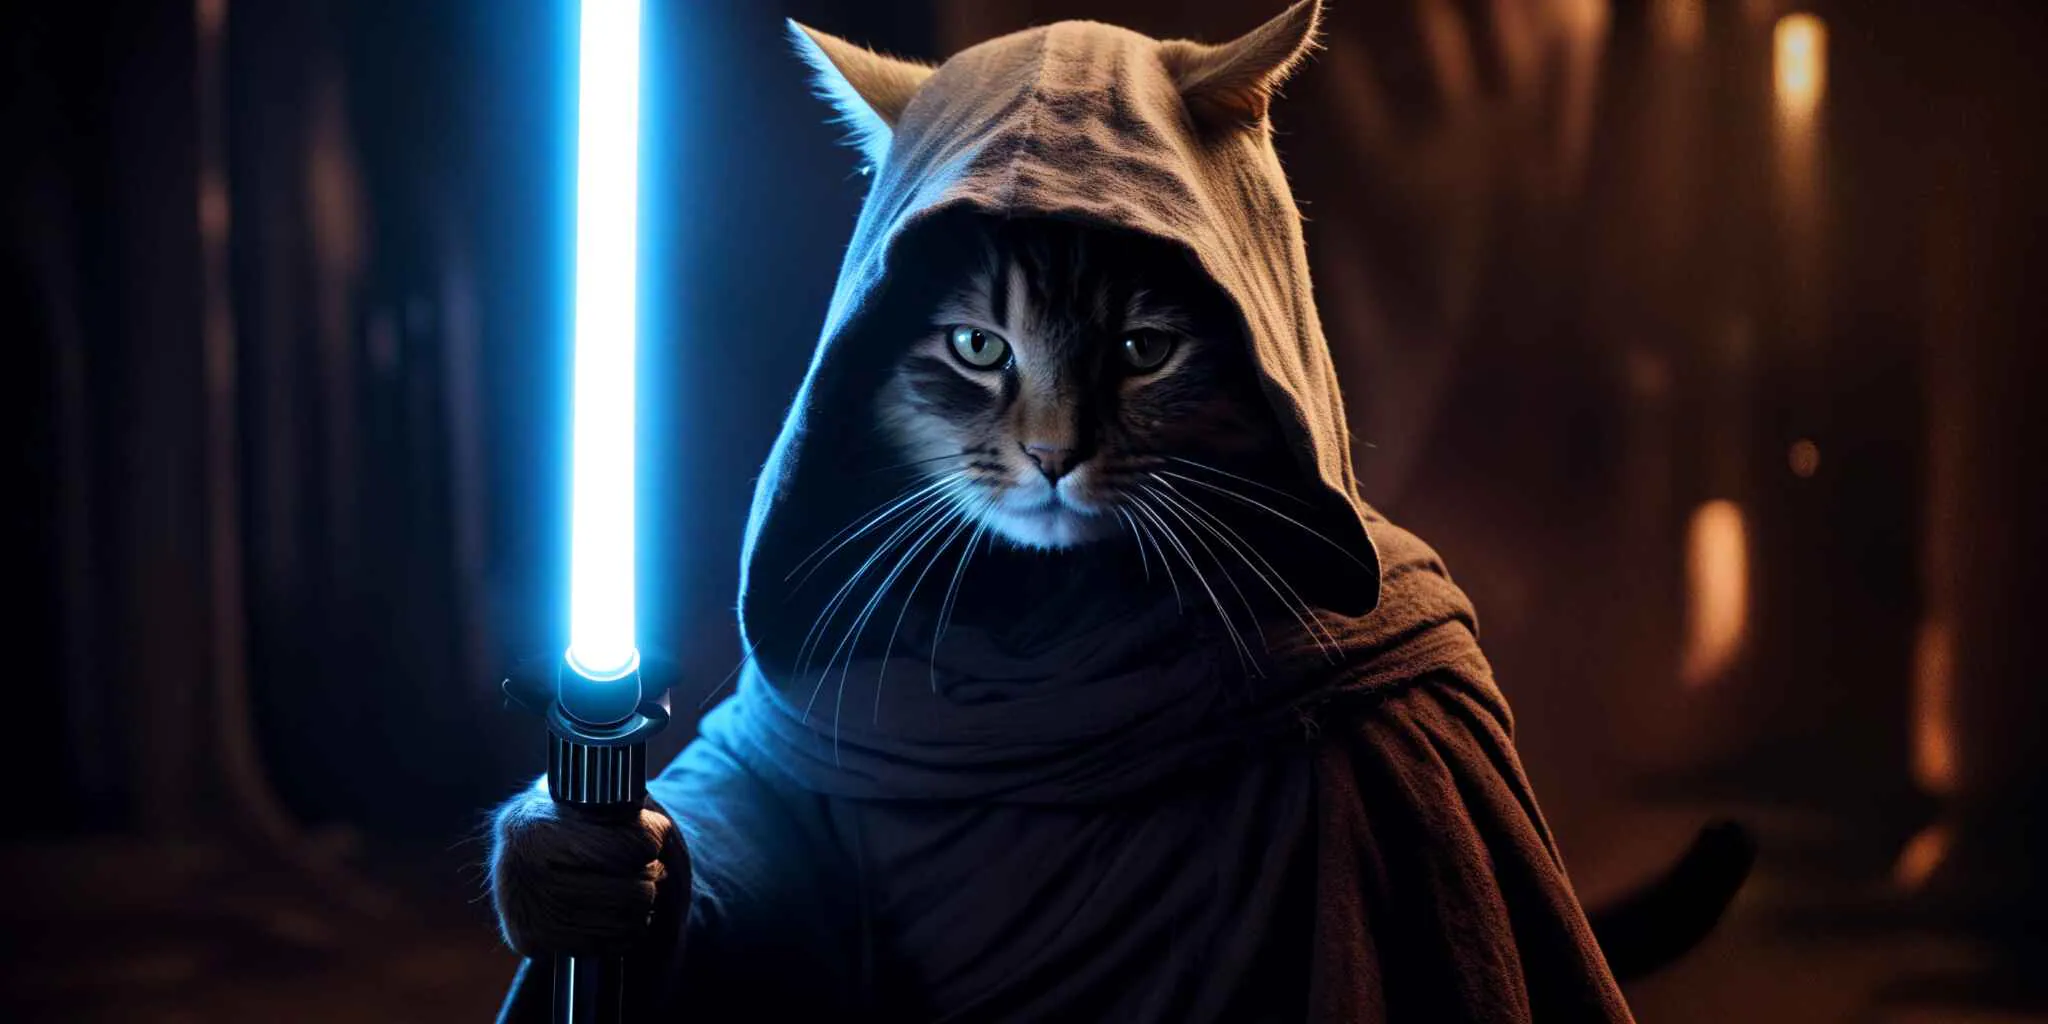
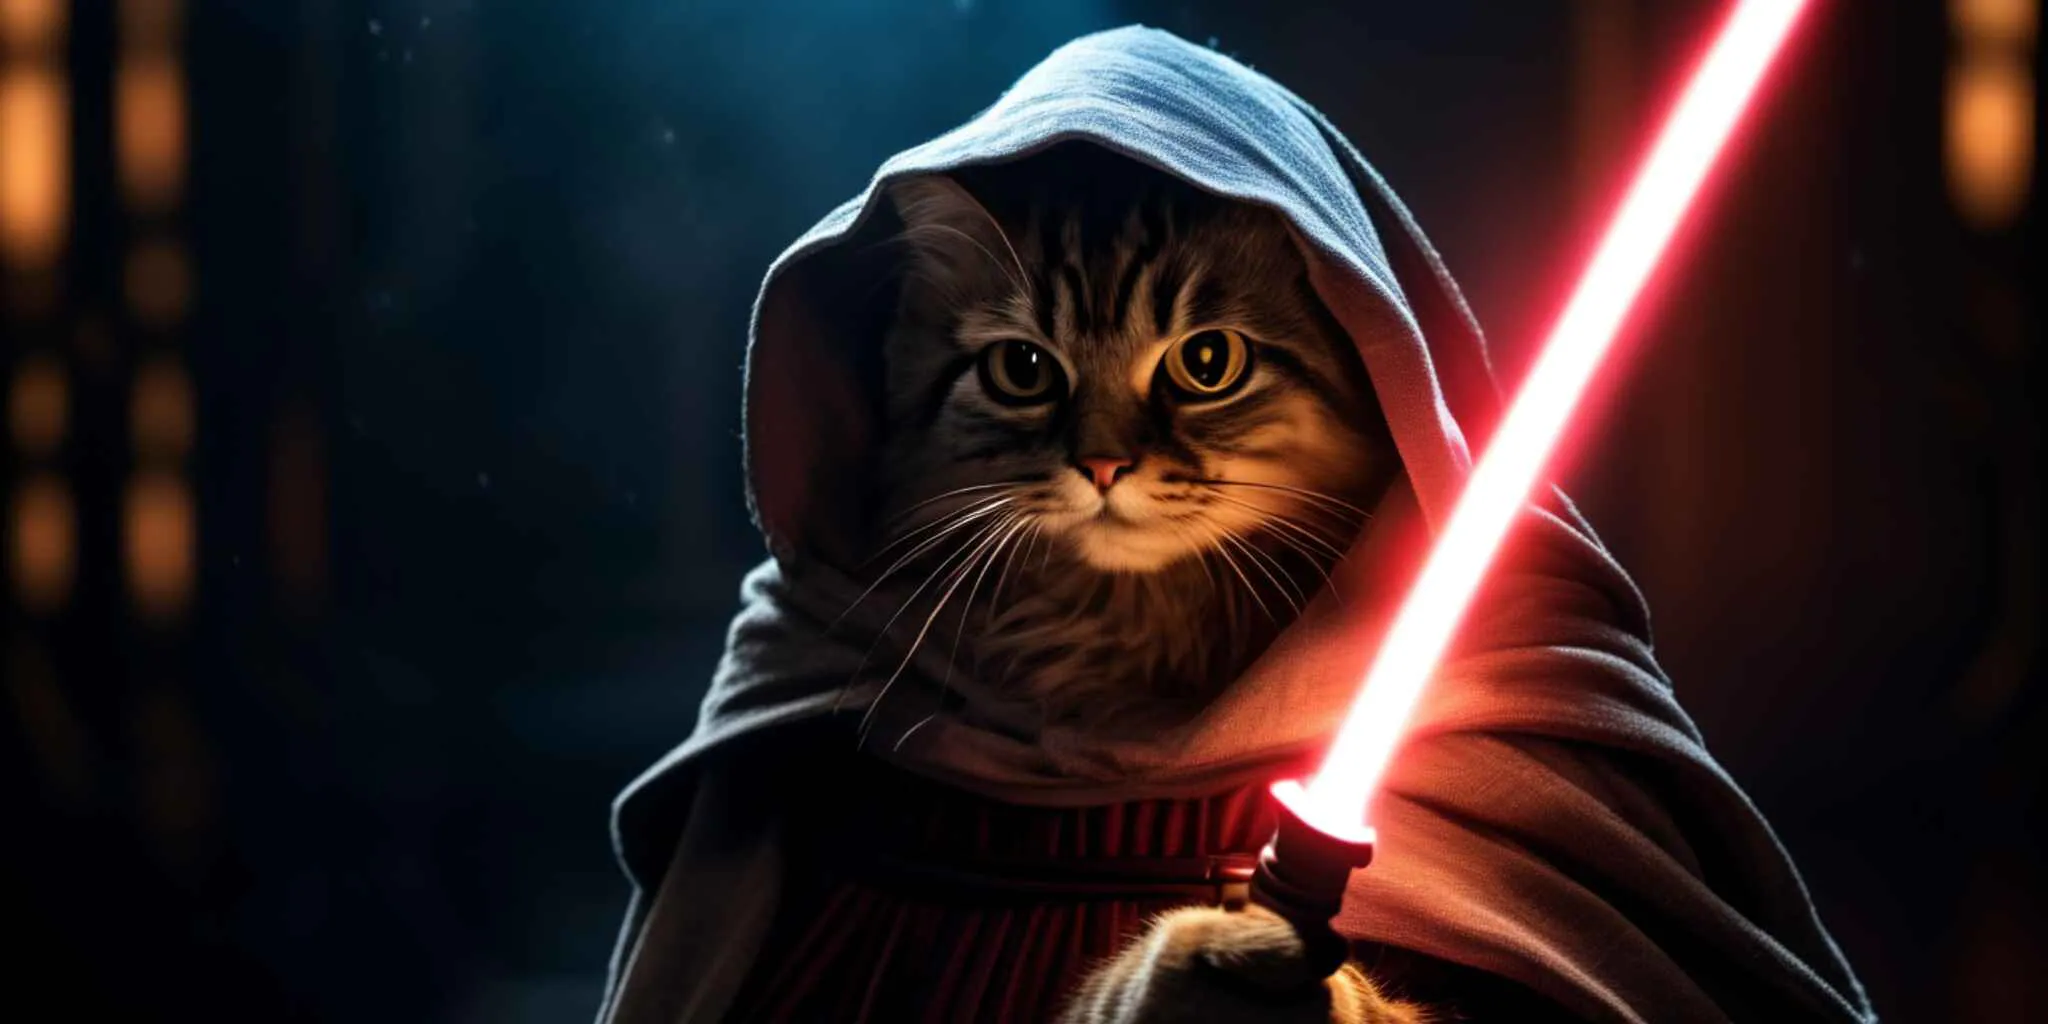
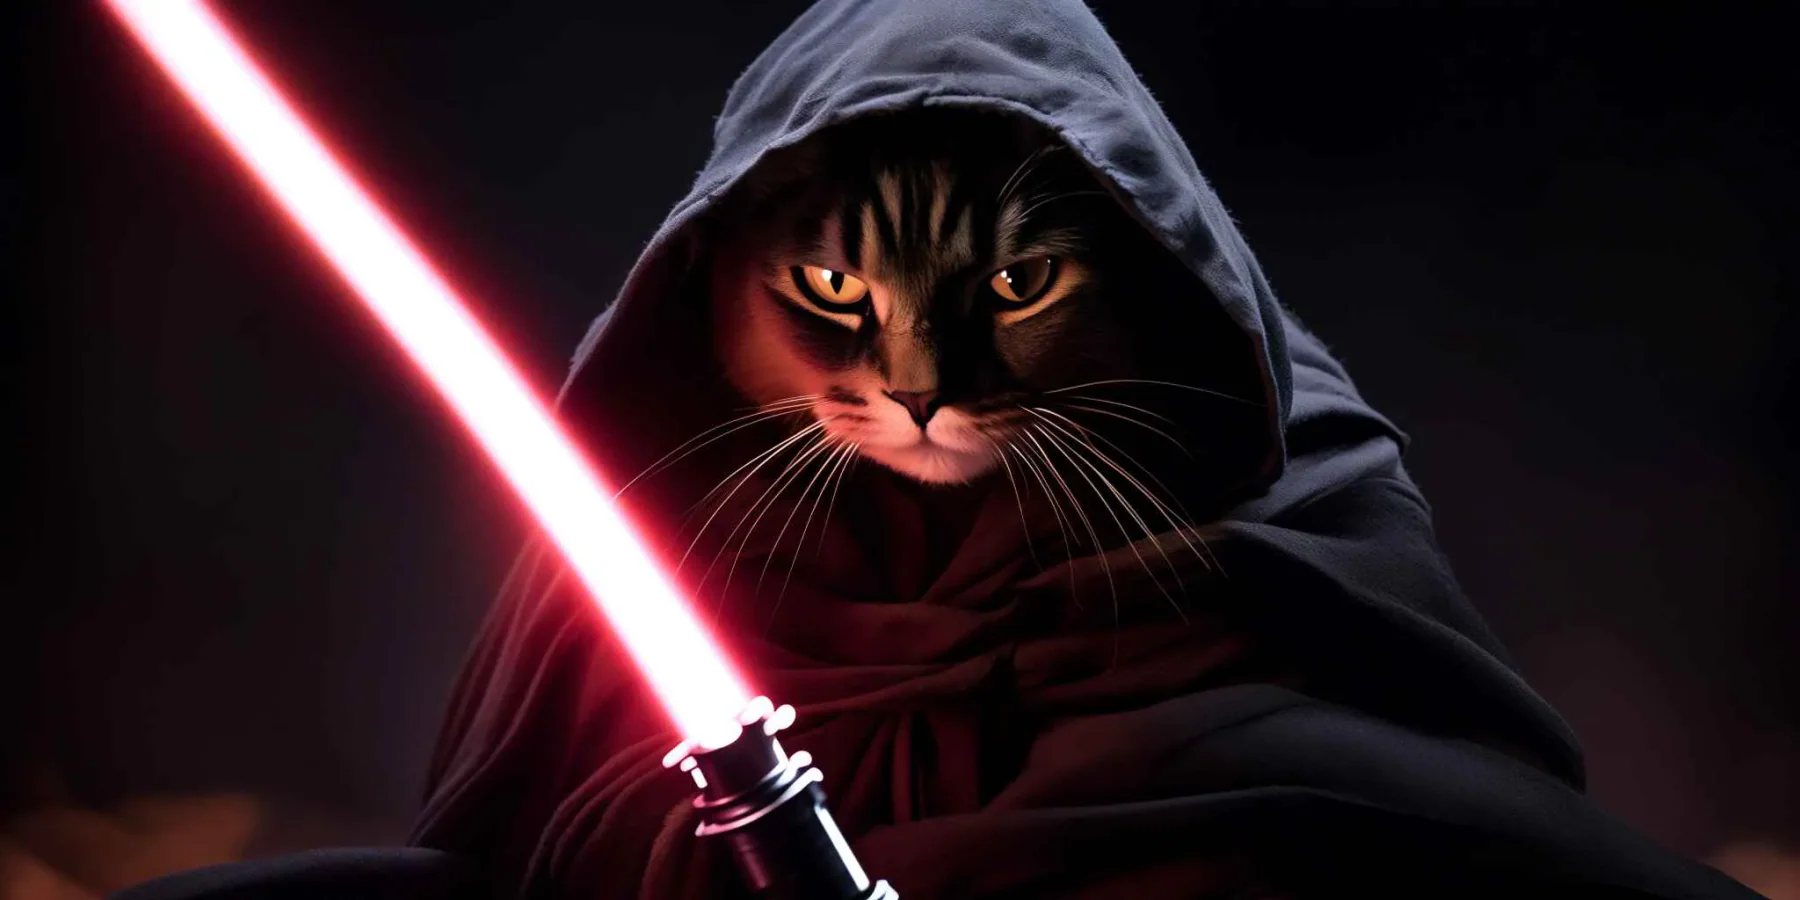
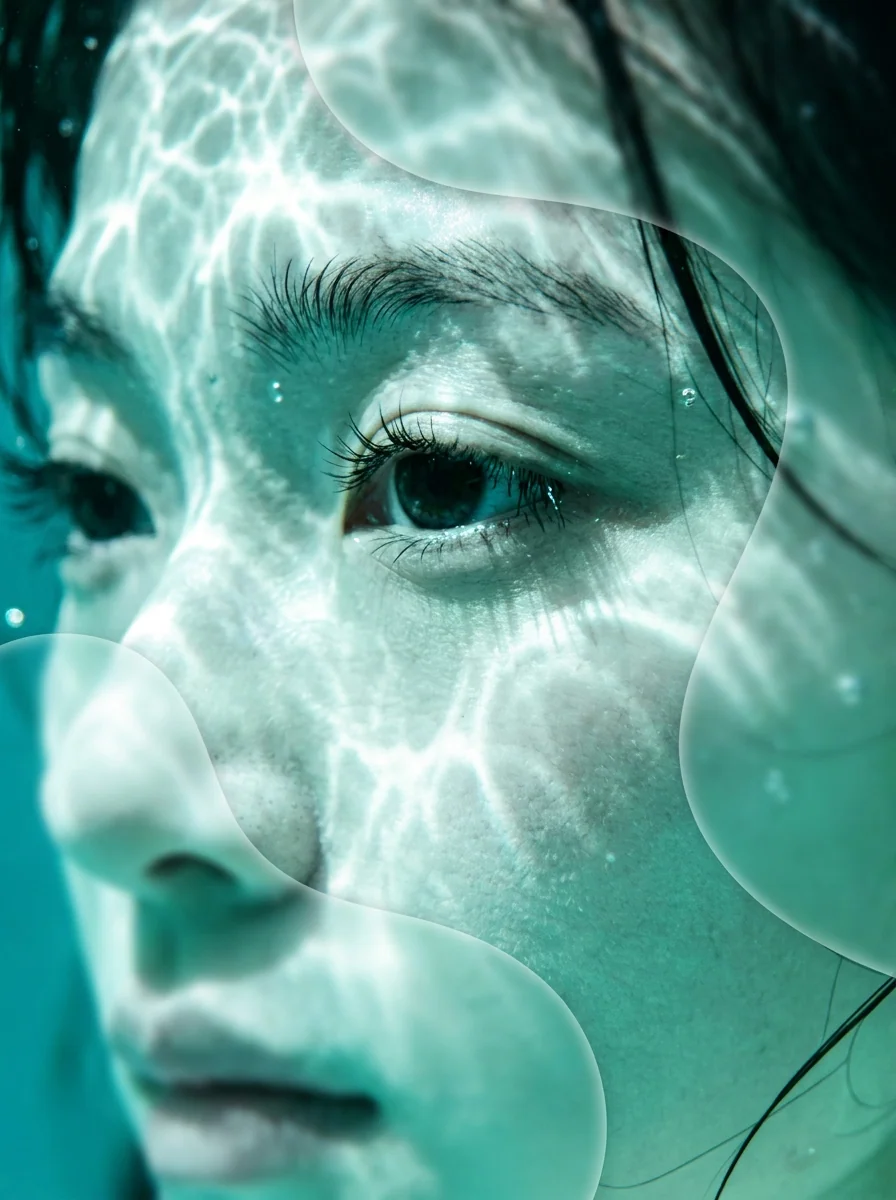
Images come back at the width and height you asked for, up to 8 per run. The four 1024 × 1024 samples here cover the same subjects as the samples on the BF16 page, so you can compare the two builds by eye.
Recommended settings
To match NVIDIA's own example for this checkpoint, set guidance scale to 4.5 and steps to 20 at 1024 × 1024. That example loads this repository's fp16 weights.
Limitations
From the card: expect imperfect photorealism, and do not count on complex legible lettering. Hands and fingers may be malformed, and busy scenes suffer from limited training data. The DC-AE autoencoder is lossy.
Safety & compliance
License: Apache 2.0, plus the Gemma Terms of Use and the Gemma Prohibited Use Policy from Google for the Gemma-2-2B-IT encoder. NVIDIA states the model is intended for research purposes only, with art and design work, educational and creative software, and research on generative models among the example research areas. The card puts true representations of people or events outside the model's scope and notes the risk of amplifying social biases.
Example prompts
Great starting points for Sana_1600M_1024px_diffusers.
API quick start
Run Sana_1600M_1024px_diffusers with a single API call.
{
  "prompt": "Cinematic photo, black panther, trending …",
  "negativePrompt": "bad, ugly, low quality",
  "steps": 25,
  "scale": 3.5
}
curl -X POST "https://api.wiro.ai/v1/Run/efficient-large-model/sana-1600m-1024px-diffusers" \
-H "Content-Type: application/json" \
-H "x-api-key: YOUR_WIRO_API_KEY" \
--data-binary @- <<'JSON'
{
"prompt": "Cinematic photo, black panther, trending …",
"negativePrompt": "bad, ugly, low quality",
"steps": 25,
"scale": 3.5
}
JSONOther models you might like
Explore similar image generation models.