Moondream3 Caption was tested on three ordinary but useful image types: a flower close-up, a coffee-pouring scene, and a dog on a leash. The aim was not to score the model against an OCR or captioning benchmark. It was to see what a production workflow can learn from six saved outputs: how length changes the result, how sampling settings change the wording, where details stay grounded, and where a caption starts making plausible guesses.
The model takes one image plus three exposed controls: length (short, normal, or long), temperature, and top_p. Its Wiro page describes temperature 0 as deterministic and calls 0.7 a sensible starting point. Lower top_p limits sampling to more likely tokens. The model page is here: Moondream3 Caption on Wiro.
What this Moondream3 Caption test set out to check
Captioning has a practical failure mode that a one-line demo often hides: an answer can sound fluent while adding a detail that the image does not prove. The flower tests a simple central subject and a blurred background. The coffee image adds an action, hands, a metal pitcher, a cup, and machinery in soft focus. The dog image checks a whole animal, a leash, accessories, and a busy but indistinct setting.
Each image appears twice where that comparison is useful. The flower checks short versus long output. Coffee compares the same normal-length request at temperature 0.7 and 0.0. The dog checks a normal default-like setting against a longer, more random one. That makes this a reading of six exact outputs, not a claim about average model accuracy or a substitute for an accessibility review.
For maker context, the official Moondream site, the Moondream Hugging Face model card, and the Moondream open-source repository were checked successfully. The public project describes Moondream as a small vision-language model for image understanding tasks such as captioning, visual question answering, and detection. This Wiro listing is specifically the caption workflow, so this article does not assume that other functions were exercised here.
Parameters, run time, and cost
| Test | Image | Length | Temperature | Top P |
|---|---|---|---|---|
| 1 | Flower | short | 0.2 | 0.9 |
| 2 | Flower | long | 0.7 | 0.95 |
| 3 | Coffee | normal | 0.7 | 0.95 |
| 4 | Coffee | normal | 0.0 | 0.95 |
| 5 | Dog | normal | 0.7 | 0.95 |
| 6 | Dog | long | 1.1 | 0.95 |
The saved six task records do not contain a separate elapsed time or charge for each output, so those figures are not reconstructed. Wiro’s model documentation includes a task-detail example that completed in 6.0 seconds with a $0.00351 total cost. That is documentation example data, not a measured average or a retroactive price for these six captions. Queue time, worker availability, and current pricing can change a fresh run. The safe way to budget a live workflow is to inspect its own completed task record.
Six outputs, read closely
1. Short flower caption: specific subject, more than a short label
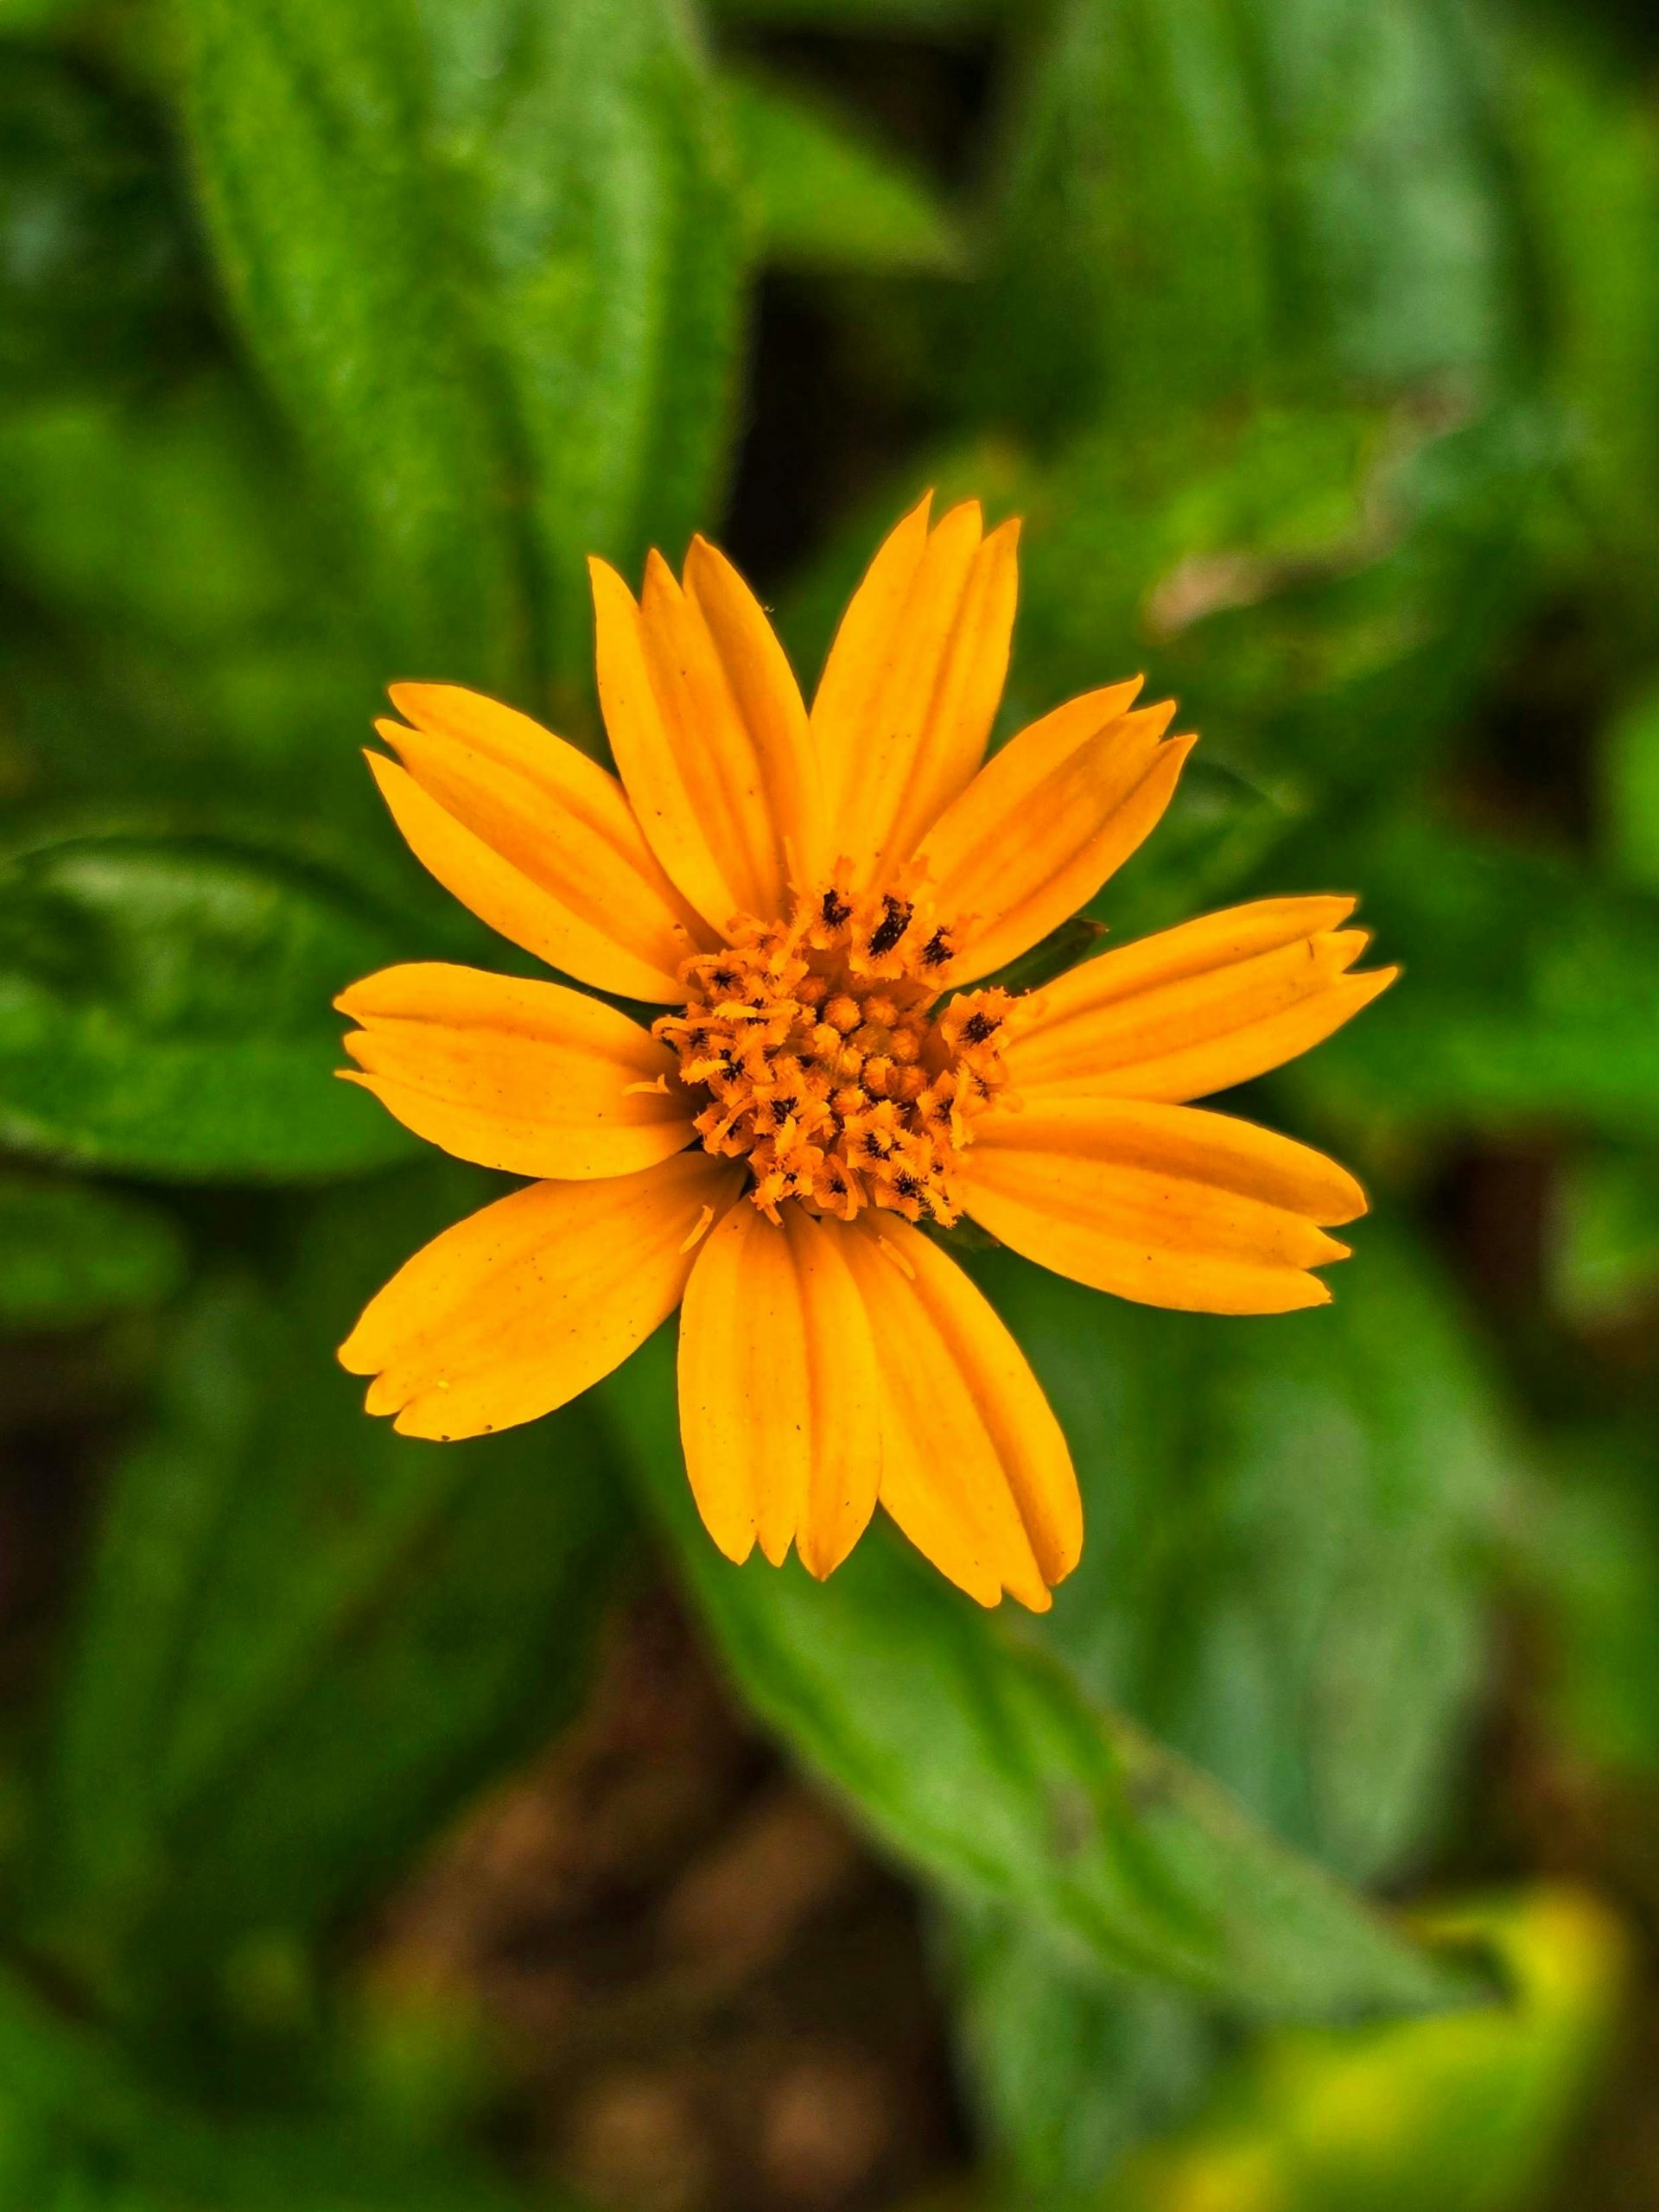
The output identifies the yellow flower, dark center, green leaves, and blurred background. It also describes six petals, curved petal shape, and contrast between yellow and green. That is useful detail for a search index or an editorial starting point, but it is longer than many teams would mean by a short alt-text draft. The key result is that the main subject remains stable and the caption does not wander into a story about the scene.
2. Long flower caption: more composition language, not much more evidence
The long request again centers the flower and blurred foliage. It adds natural-light and composition language, calling the image simple and visually appealing. Those phrases make the result read like editorial copy rather than a strict inventory caption. There is no obvious contradiction, but the comparison matters: longer output adds interpretation more readily than it adds new, decisive visual facts. Use this setting for an asset description or a human-reviewed catalog field, not for a compact label where every word must earn its place.
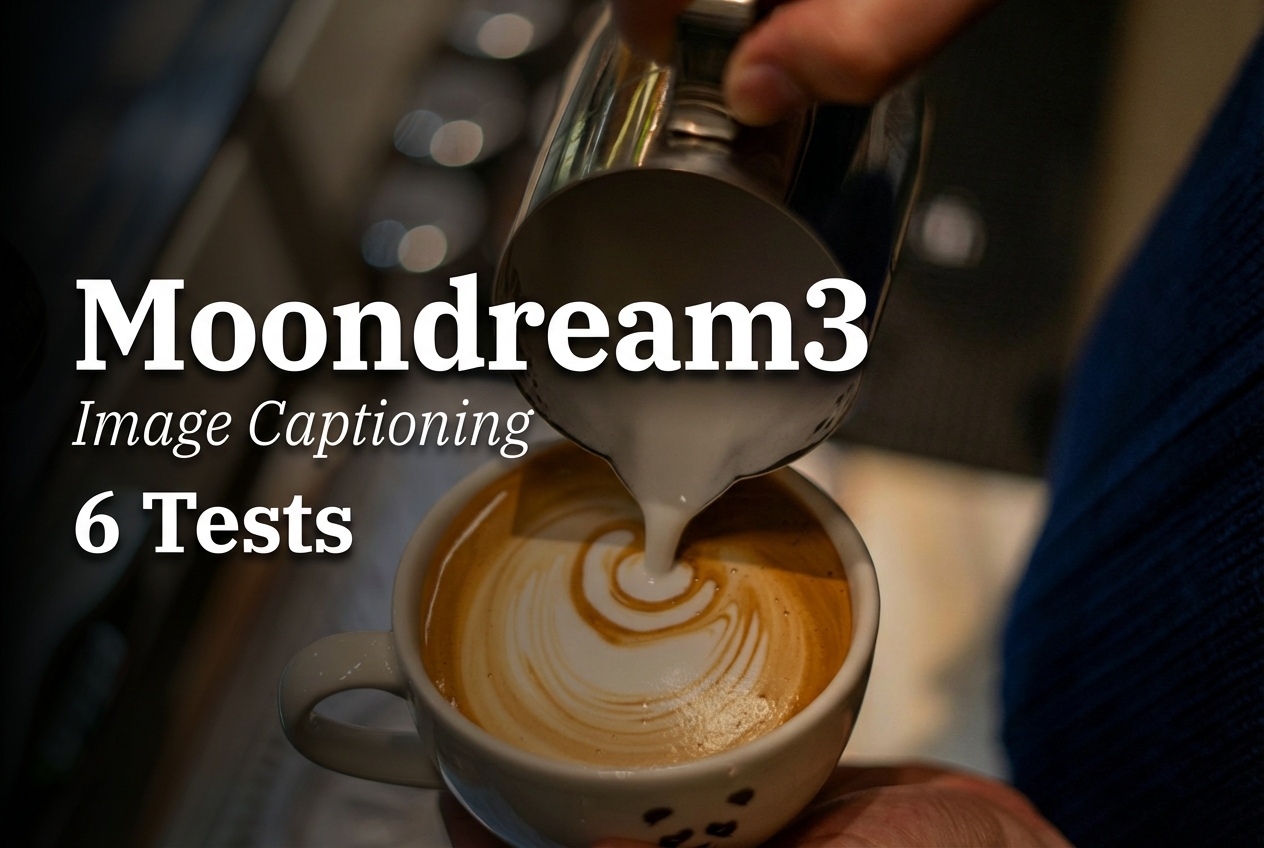
3. Normal coffee caption: action and objects hold together
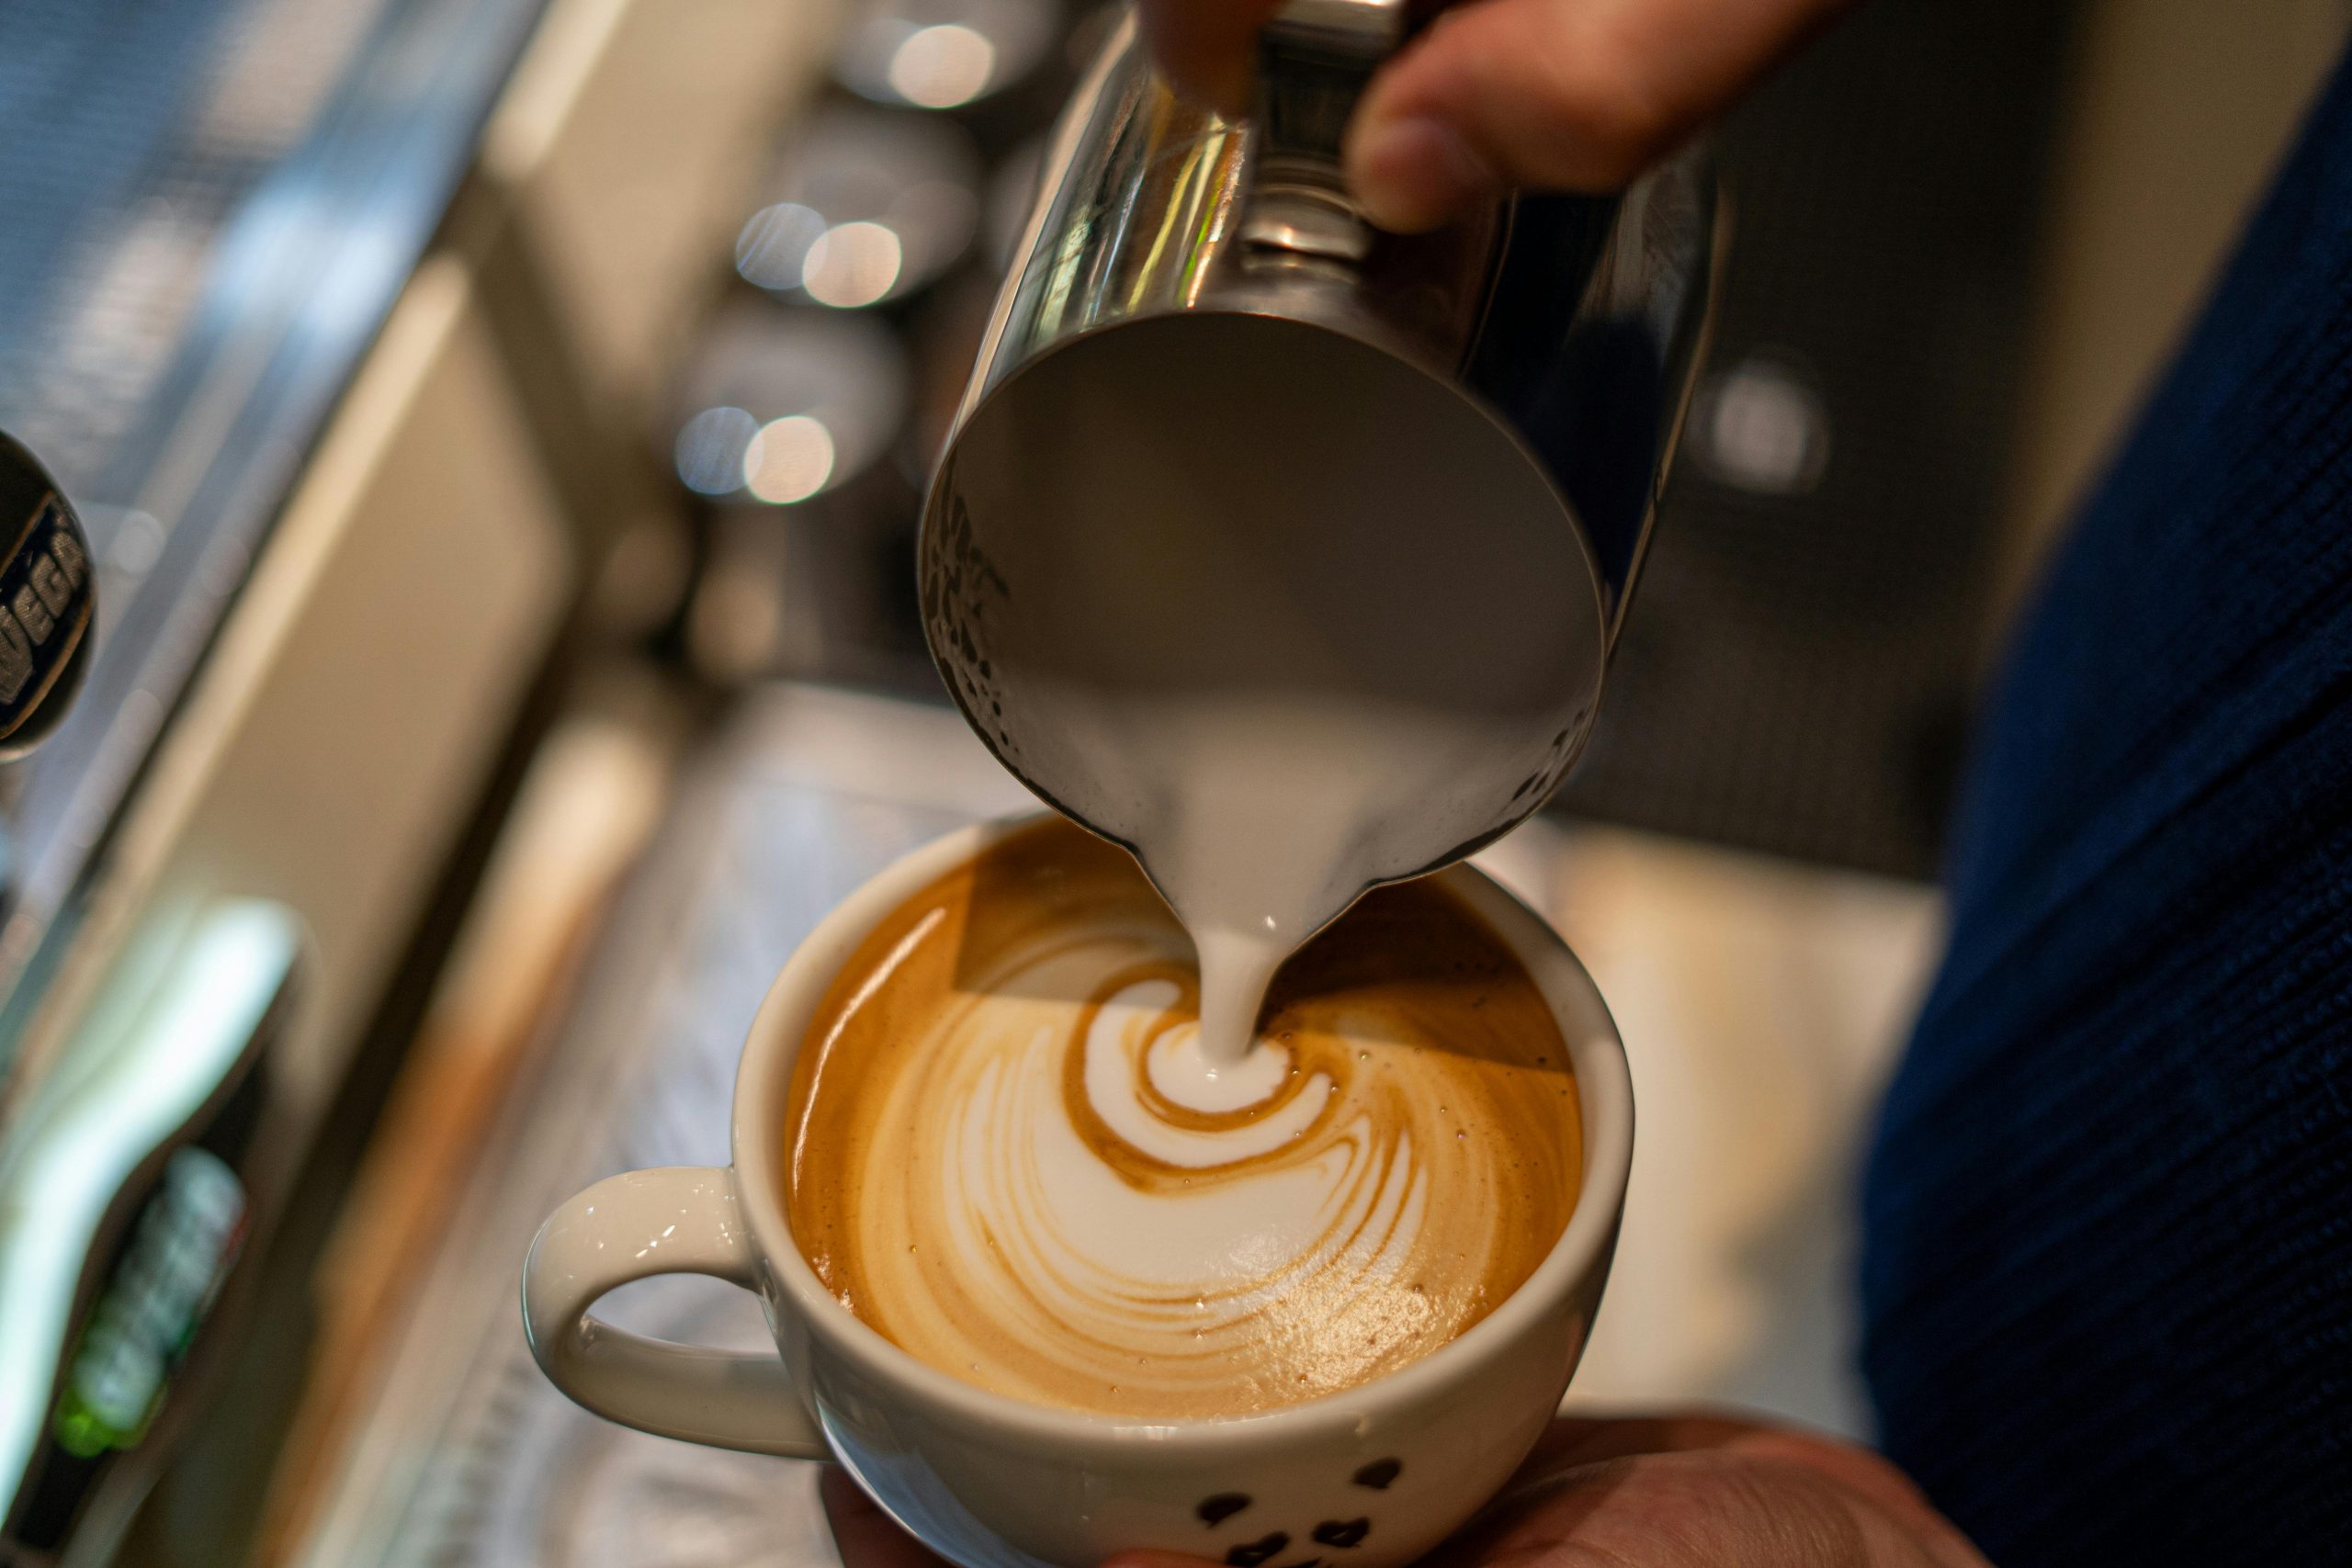
This output describes a hand pouring milk from a metallic pitcher into a white cup. It also names a coffee machine-like background and dark-blue clothing. The central action is clear, which makes this the most immediately useful result for routing, browsing, or a first-pass alt-text suggestion. The weak point is the phrase “appears to be” around the machine. That is appropriate uncertainty. A downstream system should keep that uncertainty instead of converting it into a hard fact.
4. Deterministic coffee caption: stable intent, abrupt ending
At temperature 0.0, the model still picks the same broad event: a barista pours milk into coffee from a metal pitcher. It becomes more effusive about skill and beauty, then ends mid-sentence after mentioning background lights. This is the clearest operational caveat in the set. Deterministic sampling does not guarantee a finished or minimal caption. If a caption feeds a CMS, screen reader field, or database, validate that it has terminal punctuation and impose a length guard before saving it automatically.
5. Normal dog caption: strong foreground read, tentative background detail
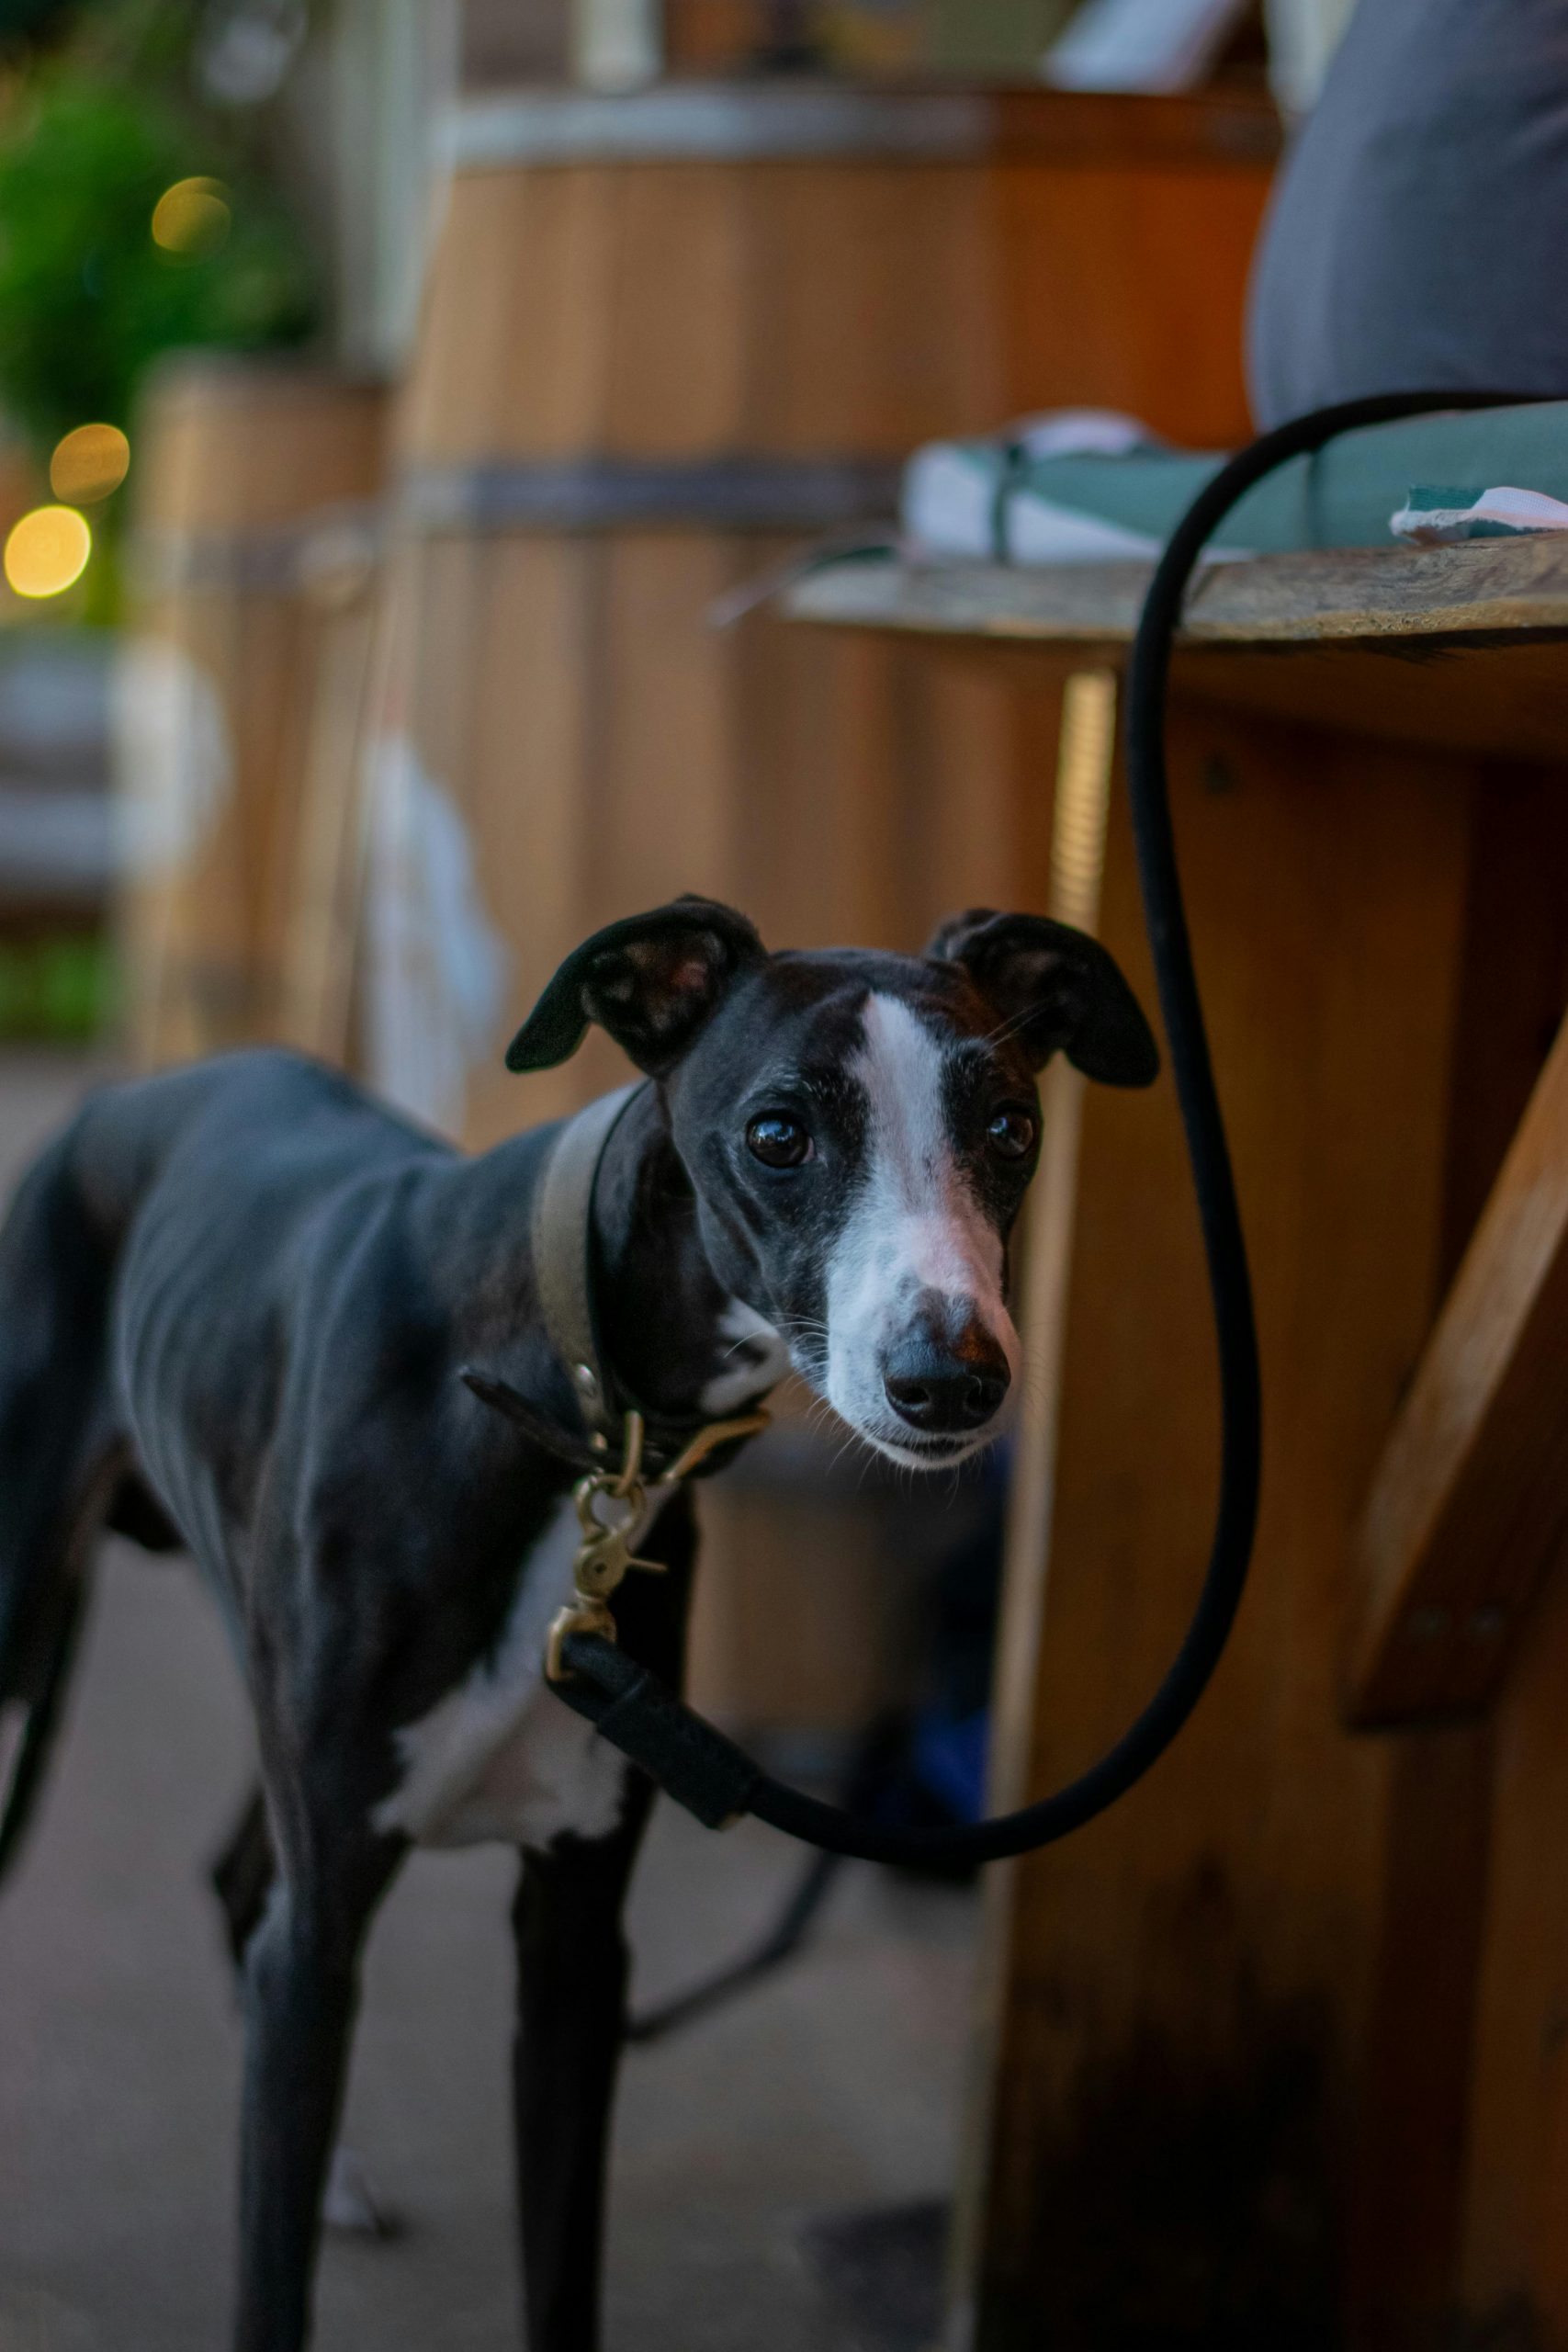
The dog, black leash, collar, tag, paved surface, and a person partly behind the table all appear in the output. It also guesses a whippet-like breed and identifies barrels and a dark wooden table. The foreground object recognition is the important win. Breed identification and blurred background context deserve a human check. For library search, the safer tags are dog, leash, collar, and pavement. A workflow should not turn “possibly a whippet” into a breed label without review.
6. Higher-temperature dog caption: the core remains, background guesses shift
The higher-temperature result keeps the dog, tan collar, leash, and asphalt. It changes the background from barrels and a table to a wooden structure that may be a fence or wall, plus green elements that may be plants or decorations. This is not a dramatic failure. It is a useful reminder that the least certain parts of a scene are where sampling choices show up first. For strict labeling or moderation queues, start at 0.0 to 0.2 and keep captions short. For a fuller prose draft that a person will edit, 0.7 is a reasonable starting point documented by the listing.
Practical scorecard
| Need | Suggested starting point | What to review |
|---|---|---|
| Asset-library tags | short, temperature 0.0-0.2 | Remove subjective language and uncertain detail |
| Alt-text draft | normal, temperature 0.2-0.7 | Check relevance, completion, and claims about people or objects |
| Editorial image description | long, temperature 0.7 | Trim mood and composition language to fit the publication |
| Strict structured labels | short, temperature 0.0 | Validate output format and send ambiguous cases to review |
When to choose Moondream3 Caption
Choose Moondream3 Caption when the job needs a fast first description of one image and the output will be inspected, normalized, or used as a helpful search hint. The flower and coffee tests show solid coverage of the main subject, action, and broad scene. It is a sensible fit for image-library triage, draft alt text, content routing, and a queue where a person confirms uncertain cases.
Choose a more constrained workflow when a caption becomes a legal, medical, safety, or product record. The dog tests show why: a fluent caption can add a plausible breed or reinterpret an indistinct background. Keep the original image available, retain uncertainty words, and never use generated wording as proof of a fact the image does not clearly show.
For related visual-model testing methods, see GPT Image 1.5 layout tests, SenseNova U1-8B layout tests, and HiDream I1 Full structured-layout tests. Each uses saved examples and inspection rather than treating one polished output as a benchmark.
Try the same images and settings with Moondream3 Caption on Wiro, then inspect the result against the image before publishing any caption as final copy.